Your AI Is Only as Smart as Your Decompiler: Binary Hacking in the Age of LLMs
Zion Leonahenahe Basque (PhD Student · Arizona State University)
DistrictCon 2026 (Year 1) · Day 1 · Mainstage
Overview
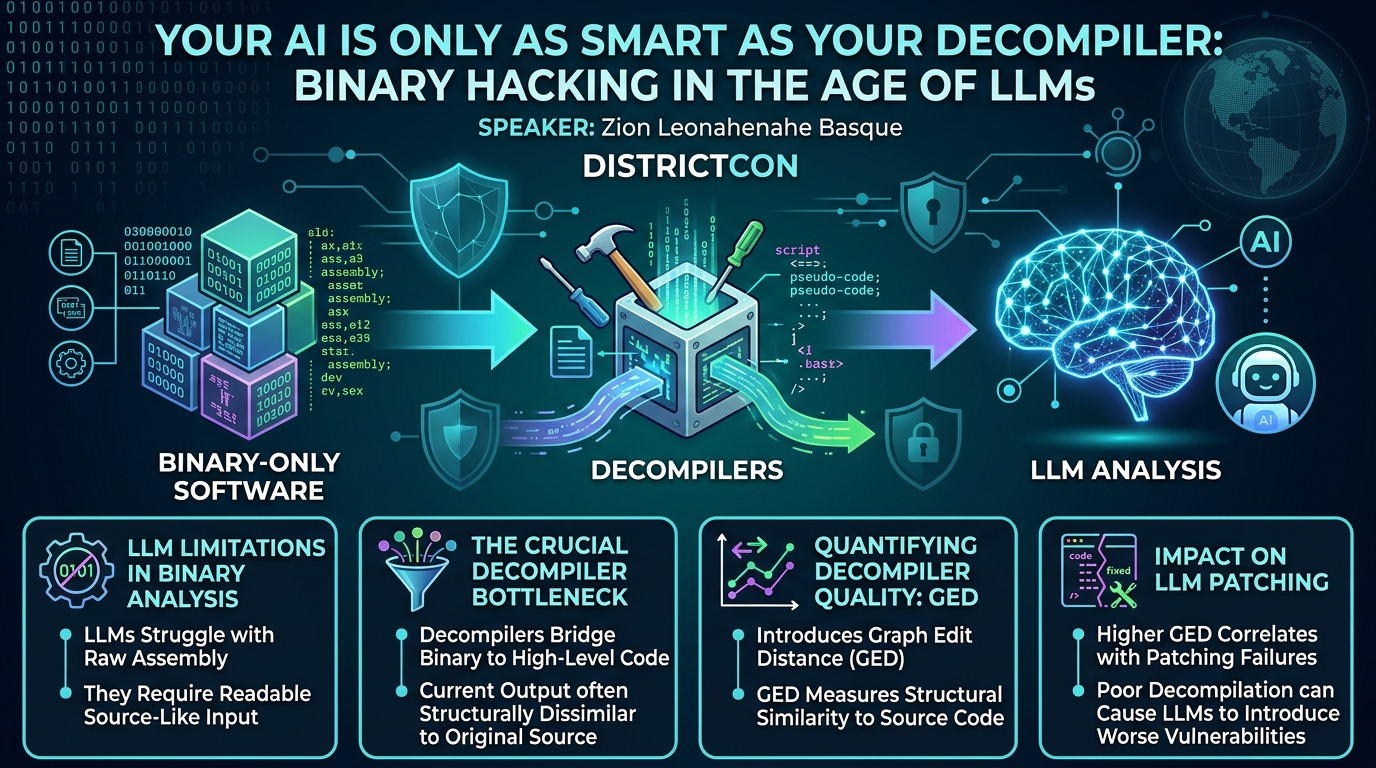
In the rapidly evolving landscape of cybersecurity, Large Language Models (LLMs) are demonstrating unprecedented capabilities in code analysis and vulnerability remediation. However, their true potential often remains untapped when confronted with binary-only software, a common scenario in critical infrastructure, embedded systems, and proprietary applications. This talk, delivered by Zion Leonahenahe Basque, a PhD student at Arizona State University, delves into the crucial, yet often overlooked, dependency of LLM-driven binary analysis on the quality of decompilers.
Key moments
- 2:00 LLMs scale to large codebases, unlike symbolic execution.
- 3:00 DARPA AICC: LLMs found 18 zero days for $150.
- 6:00 Why decompilers' 'garbage' output fails LLMs.
- 8:00 Nginx case study: Poor decompilation leads to dangerous patches.
- 12:00 Graph edit distance quantifies decompiler quality for LLMs.
- 14:00 15% success rate: Graph edit distance predicts LLM performance.
- 17:00 Decompilers average 22 edits; significant improvement is possible.
- 19:00 Call to action: Improve decompilers for LLM binary analysis.
Your AI Is Only as Smart as Your Decompiler: Binary Hacking in the Age of LLMs
Speakers: Zion Leonahenahe Basque, PhD Student, Arizona State University
Conference: DistrictCon
YouTube: https://www.youtube.com/watch?v=ncYo6ZqSRLw
Overview
In the rapidly evolving landscape of cybersecurity, Large Language Models (LLMs) are demonstrating unprecedented capabilities in code analysis and vulnerability remediation. However, their true potential often remains untapped when confronted with binary-only software, a common scenario in critical infrastructure, embedded systems, and proprietary applications. This talk, delivered by Zion Leonahenahe Basque, a PhD student at Arizona State University, delves into the crucial, yet often overlooked, dependency of LLM-driven binary analysis on the quality of decompilers.
Basque highlights a critical bottleneck: while LLMs excel at processing human-readable source code, they struggle immensely with raw binary or assembly. Decompilers are meant to bridge this gap by translating machine code back into a high-level, C-like representation. However, as the research presented demonstrates, current decompilers often produce output that, while functionally equivalent, is structurally dissimilar to the original source code. This structural divergence, quantified by a novel metric called Graph Edit Distance (GED), profoundly impacts an LLM's ability to accurately identify vulnerabilities, root causes, and generate correct patches, sometimes leading to the introduction of even more severe bugs.
The significance of this research is profound for the future of automated security. As LLMs become more integrated into vulnerability research and patching workflows, understanding and improving the quality of their input—especially from decompilers—is paramount. Basque's work not only exposes a critical weakness in the current LLM-binary analysis pipeline but also offers a quantifiable method to assess decompiler performance and advocates for a renewed focus on generating source-like decompilation. This talk serves as a wake-up call for both decompiler developers and security practitioners leveraging LLMs, emphasizing that the intelligence of an AI for binary analysis is fundamentally constrained by the fidelity of its decompiler.
Background
▶ Watch: LLMs scale to large codebases, unlike symbolic execution. (2:00)
The increasing complexity and sheer volume of modern software pose significant challenges for traditional security analysis techniques. Programs are now routinely exceeding 100,000 lines of code, with popular open-source projects like Engine X, SQLite, and libxml serving as prime examples. Conventional symbolic execution, a powerful formal analysis method, typically scales to only hundreds, or at best, a thousand lines of code, making it impractical for large-scale projects. In contrast, LLMs have demonstrated the ability to process and reason about codebases orders of magnitude larger, often handling up to 10,000 lines within their context windows, a capacity that is continuously expanding.
The potential of LLMs in cybersecurity was rigorously tested by DARPA through its AI Cyber Challenge (AICC), a two-year program designed to push the boundaries of autonomous vulnerability discovery and patching. Various scientific teams and businesses developed Cyber Reasoning Systems (CRSs) aimed at autonomously ingesting large open-source projects, identifying zero-days, and generating patches. The results were compelling: across these systems, approximately 18 zero-days were discovered in projects that had never been seen before by the CRSs, often exceeding 100,000 lines of code. Crucially, these "free zero-days" were found at an average cost of only $152 in LLM API credits, highlighting the economic viability and scalability of this approach. This success indicates that 2026 marks the advent of a new era of LLM-driven hacking.
Despite these impressive results, making LLMs perform effectively in security tasks requires significant expertise, particularly in validating both input and output. Most AICC successes relied on high-quality, readily available source code, which allowed for sophisticated formal analyses before engaging the LLM and rigorous validation afterward. However, a significant portion of the software ecosystem operates without accessible source code. Critical systems such as drones, autonomous vehicles, and medical devices often exist only as compiled binaries. When presented with raw binary data or assembly, LLMs falter, as their training data primarily consists of structured, human-readable source code.
This is where decompilers traditionally step in, acting as the crucial intermediary by attempting to reverse-engineer machine code back into high-level programming language constructs. The naive assumption is that a decompiler can simply convert a binary into source code, which an LLM can then process to find bugs. However, this assumption is fundamentally flawed. As Basque explains, decompilers do not produce actual source code; they generate a functionally equivalent, but often structurally distinct, representation. For instance, a few lines of original source code might decompile into a significantly expanded version with numerous artificial function calls, inexplicable goto statements, and rearranged if conditions, making the code much harder for an LLM to reason about effectively, unlike a human reverse engineer who can intuitively navigate these discrepancies.
Key Findings
▶ Watch: Why decompilers' 'garbage' output fails LLMs. (6:00)
The core finding of this research is that the structural similarity between decompiled code and its original source code is a critical determinant of an LLM's success in security tasks like vulnerability patching. Even minor structural deviations can lead to drastically different, and often detrimental, outcomes.
Basque presented a compelling case study involving Engine X, a major target in the DARPA AICC program. A known vulnerability, an artificial heap buffer overflow, was introduced into the send_file function. This bug stemmed from allocating a constant size (100 bytes) for a dynamically sized input, allowing for overflows when files larger than 100 bytes were processed. The correct patch involved replacing the constant allocation with the dynamic size argument from the function prototype.
The experiment involved stripping the Engine X binary (retaining function names) and feeding its decompiled output from two different decompilers—Angr and Ghidra—to a Cyber Reasoning System (CRS) powered by an LLM. Both LLMs, when given their respective decompilations, correctly identified the root cause as a heap buffer overflow. However, their patching outcomes diverged dramatically:
- The LLM fed with Angr's decompilation (which was structurally very close to the original source) successfully generated the correct patch.
- The LLM fed with Ghidra's decompilation (which exhibited structural differences) generated a "crazy patch" after five attempts. This patch, instead of using the dynamic
sizeparameter, simply increased the constant allocation to 100,000 bytes. While this might prevent the specific Proof-of-Concept (POC) exploit used in the test (which was only 1,000 bytes), it introduced a new, potentially worse vulnerability: a massive over-allocation of memory that could lead to denial-of-service or other resource exhaustion issues. This highlights the danger of LLM-generated patches based on poor decompiler output.
To quantify these structural differences, the research introduced the concept of Graph Edit Distance (GED), an algorithm that measures the minimum number of graph operations (insertions, deletions, substitutions of nodes or edges) required to transform one control flow graph (CFG) into another. In the Nginx case study, the Ghidra decompilation had a GED of 6 edits compared to the source code, while the Angr decompilation had a GED of 0 edits, perfectly matching the source's structure. This stark difference in structural fidelity directly correlated with patching success.
Further scaling this observation, the study analyzed all 14 AICC bugs in Nginx across Angr, Ghidra, and IDA Pro decompilers, with three trials each. The overall success rate for patching these bugs using decompilation was a mere 15%, a stark contrast to the ~90% success rate achieved when LLMs operated directly on source code during the AICC competition. Only 5 out of 14 unique patches were successfully generated from decompiled code, compared to the 14 out of 14 typically achieved with source.
A crucial statistical finding emerged: successful patches almost exclusively occurred when the decompilation provided to the LLM had a GED of three edits or less on average, whereas failures were associated with decompilations having 12 edits or more on average. This quantitatively demonstrates that GED is a strong indicator of how useful a decompilation will be for LLM-driven tasks.
When examining the average GED produced by the decompilers on the Nginx dataset (not just the patched functions), Angr averaged 10 edits, IDA averaged 8 edits, and Ghidra averaged 14 edits. The speaker emphasized that LLMs are not human experts; they do not possess the same adaptability to small structural changes. Moving an if statement twice, a seemingly minor alteration to a human, can completely derail an LLM.
Expanding the analysis to a larger dataset of 26 benign Debian packages (comprising approximately 8,000 function pairs), the research revealed that even the best decompilers (IDA Pro and Angr) produced an average GED of 22 edits compared to their original source code. This significant average distance (equivalent to at least five if statement movements or the complete restructuring of loops and goto statements) highlights the substantial gap between current decompiler output and true source code likeness. Encouragingly, the Angr decompiler, through dedicated research, improved its average GED from an "obscene" 45 edits in 2022 to 22.64 edits in 2024, demonstrating that substantial improvements are achievable with focused effort.
Technical Deep Dive
▶ Watch: Graph edit distance quantifies decompiler quality for LLMs. (12:00)
The technical foundation of this research rests on two pillars: the concrete example of an LLM failing to patch a vulnerability due to poor decompiler output, and the introduction of Graph Edit Distance (GED) as a quantifiable metric for decompiler quality in the context of LLM analysis.
Let's revisit the Nginx send_file vulnerability. The original source code contained a function designed to send files. Within this function, there was an allocation call, EngineX_alloc, intended to reserve memory for the file data. The vulnerability arose because this allocation was hardcoded to 100 bytes, EngineX_alloc(100), while the file size, passed as an argument (let's call it size), could be arbitrarily larger. This constant allocation for a dynamically sized input created a classic heap buffer overflow. The correct patch simply involved changing the allocation to EngineX_alloc(size), using the dynamic size argument.
When this vulnerable function was compiled and then decompiled, the output varied significantly between Angr and Ghidra.
- Angr's decompilation for this specific function, while containing some common decompiler artifacts like
0xffconstants and generic argument names (e.g.,A2forsize), maintained a largely linear control flow structure. Theifstatements and their nesting closely resembled the original source. - Ghidra's decompilation, conversely, displayed a more complex and deeply nested control flow. While also exhibiting decompiler artifacts, the arrangement of
ifstatements and the overall structural organization were notably different. For instance, a condition that might be a simpleifin the source could become multiple nestedifs or be intertwined withgotostatements in the decompiled output, even if the logical outcome was identical.
The LLMs, when tasked with identifying the root cause and generating a patch, were given not only the decompiled code but also a crash trace or a Proof-of-Concept (POC) that demonstrated the overflow. Both LLMs correctly deduced that a heap buffer overflow was occurring due to an undersized allocation. However, the subsequent patching phase highlighted the critical impact of structural fidelity.
- The LLM processing Angr's output, benefiting from its source-like structure (GED of 0), could accurately map the
A2argument (representingsize) to the allocation function and correctly proposeEngineX_alloc(A2). - The LLM processing Ghidra's output, despite the correct root cause analysis, struggled with the structurally divergent code (GED of 6). Instead of identifying the correct dynamic
sizeargument within the convoluted control flow, it resorted to a heuristic-based "fix": vastly increasing the constant allocation toEngineX_alloc(100000). This demonstrates an LLM's tendency to find a superficial fix that passes the immediate test case (the POC) without understanding the true underlying logic, especially when the code structure obfuscates it.
The Graph Edit Distance (GED) metric is central to quantifying this structural difference. To calculate GED:
- Construct Control Flow Graphs (CFGs): For both the original source code and the decompiled output of a function, a CFG is generated. Nodes in the CFG represent basic blocks (sequences of instructions with a single entry and exit point), and edges represent possible control flow transitions (e.g., jumps, conditional branches).
- Compare CFGs: The GED algorithm then determines the minimum number of elementary graph operations (node insertion/deletion, edge insertion/deletion, node/edge attribute substitution) required to transform one CFG into the other. This is an NP-hard problem in its exact form, but approximation algorithms are employed for practical use.
- Interpretation: A lower GED indicates greater structural similarity. The research established a rule of thumb: approximately three graph edits correspond to one significant
ifstatement modification. Thus, a GED of 6, as seen with Ghidra's output for the Nginx example, implies significant structural changes (e.g., twoifstatements being moved or restructured) compared to the original source.
The statistical analysis further cemented the importance of GED. On the Nginx dataset, Angr and IDA Pro generally produced lower average GED values (10 and 8 edits, respectively) compared to Ghidra (14 edits). This difference, though seemingly small, translated into a substantial disparity in patching success rates. The broader analysis across 26 Debian packages showed an average GED of 22 edits even for leading decompilers, illustrating the widespread challenge of obtaining source-like decompilation. This means that, on average, decompilers introduce structural changes equivalent to moving or restructuring about seven if statements, or completely transforming loops and goto structures, making the code significantly harder for LLMs to reason about with high fidelity.
Demo / Proof of Concept
▶ Watch: 15% success rate: Graph edit distance predicts LLM performance. (14:00)
While the talk did not feature a live, interactive demonstration in the traditional sense, the comprehensive Nginx patching case study served as its primary proof of concept. This in-depth analysis effectively illustrated the core hypothesis: the quality of decompiler output directly dictates the success or failure of LLM-driven binary security tasks.
The demonstration unfolded through a detailed comparison of how an LLM-powered Cyber Reasoning System (CRS) attempted to patch a specific vulnerability in the send_file function of the Nginx web server. The vulnerability, artificially introduced for the AICC program, was a heap buffer overflow stemming from a constant memory allocation of 100 bytes (EngineX_alloc(100)) for a file whose size (size) could be much larger. The correct fix was to dynamically allocate memory based on the actual file size: EngineX_alloc(size).
The speaker presented the original source code snippet, clearly showing the size parameter in the function prototype and the erroneous constant allocation. He then showed the decompiled outputs from two different decompilers: Angr and Ghidra.
- Angr's decompilation: Visually, Angr's output for this function maintained a relatively linear control flow. Although it contained generic variable names (e.g.,
A2for thesizeparameter) and some decompiler-specific constructs, its overall structure, particularly the arrangement of conditional statements, closely mirrored the original source code. This was later quantified by a Graph Edit Distance (GED) of 0 compared to the source for this specific function, indicating perfect structural fidelity. - Ghidra's decompilation: In contrast, Ghidra's output for the same function exhibited a more complex and nested control flow. The
ifstatements were more deeply indented and sometimes rearranged, and the overall "flow" felt less natural compared to the source. This structural divergence was later quantified with a GED of 6 relative to the source, implying significant changes in the control flow graph.
The critical part of the proof of concept was the outcome of the LLM's patching attempts:
- Root Cause Analysis: Both LLMs, when presented with their respective decompilations and a crash, successfully identified the vulnerability as a heap buffer overflow caused by an undersized allocation. This confirmed that LLMs could perform basic reasoning even on imperfect decompiled code.
- Patch Generation (Angr): The LLM using Angr's decompilation generated the correct patch. It successfully identified
A2as the dynamic size parameter and correctly modified the allocation call to useEngineX_alloc(A2). This demonstrated that when the decompiler output closely resembles the source, LLMs can perform highly accurate remediation. - Patch Generation (Ghidra): The LLM using Ghidra's decompilation, despite the correct root cause analysis, produced an incorrect and dangerous patch. After five attempts, it settled on changing the allocation from 100 bytes to 100,000 bytes (
EngineX_alloc(100000)). While this "fixed" the immediate POC (which was designed for a 1,000-byte overflow), it introduced a severe resource exhaustion vulnerability through massive over-allocation. This highlighted that structural differences, even if semantically equivalent to a human, can lead an LLM to generate syntactically plausible but semantically flawed and dangerous "fixes."
This detailed comparison effectively served as a proof of concept, demonstrating that the fidelity of decompiler output, specifically its structural similarity as measured by GED, is a direct and critical factor in the success of LLM-driven binary security analysis and patching. It underscored the potential for LLMs to introduce new, critical vulnerabilities when working with structurally poor decompilation, thereby emphasizing the urgent need for decompiler improvement.
Defensive Implications
▶ Watch: Call to action: Improve decompilers for LLM binary analysis. (19:00)
The findings presented by Zion Basque carry significant defensive implications for organizations and security practitioners engaging with LLM-driven security tools, particularly in contexts involving binary analysis. The primary takeaway is a stark warning: blindly trusting LLM-generated patches or analyses derived from decompiled code can introduce new, potentially more severe vulnerabilities.
Here are the key defensive implications:
- Decompiler Quality is a Critical Prerequisite for LLM Trustworthiness: Security teams leveraging LLMs for binary analysis must recognize that their AI is only as good as the decompiler providing its input. The quality of decompilation, specifically its structural likeness to source code (quantified by Graph Edit Distance (GED)), directly impacts the LLM's ability to reason accurately and generate correct fixes. Relying on decompilers that produce high GED outputs risks superficial fixes that mask original bugs or introduce new ones, as demonstrated by the Nginx case study.
- Diversify Decompiler Usage and Validate Outputs: In scenarios where source code is unavailable, defenders should adopt a strategy of using multiple decompilers (e.g., Angr, IDA Pro, Ghidra) and comparing their outputs. As Basque noted, during runtime, the GED for a given function is unknown. By using a diverse set of tools, security teams can increase the likelihood of obtaining at least one decompilation that is structurally close enough to the source for an LLM to process effectively. However, this only mitigates the problem; it does not eliminate the need for validation.
- Mandatory Human Validation of LLM-Generated Patches: The Nginx example, where an LLM introduced a 100,000-byte over-allocation, underscores the critical need for rigorous human review and validation of any patch generated by an LLM from decompiled code. Automated testing alone might not catch these subtle, new vulnerabilities if the test cases only target the original bug. Human experts must scrutinize the LLM's reasoning and the resulting patch for correctness, efficiency, and the absence of new side effects. This means LLMs are currently best used as powerful assistants, not autonomous agents, in binary patching workflows.
- Advocate for Decompiler Improvement and Prioritize GED: The security community, including researchers and practitioners, needs to actively engage with decompiler developers to prioritize improvements in generating source-like code. The Graph Edit Distance (GED) should become a standard metric for evaluating decompiler quality, especially in the context of LLM integration. Defenders should push for decompilers that aim for lower GED values, making their outputs more amenable to advanced AI analysis. The demonstration that Angr's GED was significantly reduced in two years shows that improvement is possible with focused research.
- Awareness of LLM Limitations in Non-Deterministic Environments: LLMs exhibit non-deterministic behavior, and small input changes can lead to vastly different outputs. When dealing with the inherent inaccuracies and structural variations of decompiled code, this non-determinism can be particularly problematic. Defenders should be aware that repeated attempts with an LLM on the same flawed decompilation might yield different "patches," some of which could be worse than others. This reinforces the need for robust validation processes.
In essence, while LLMs offer exciting prospects for scaling security analysis to binaries, their effectiveness is intrinsically tied to the quality of the decompilation. Defenders must approach LLM-driven binary security with a healthy dose of skepticism, implementing multi-faceted validation strategies, diversifying their toolchain, and advocating for fundamental improvements in decompiler technology to truly harness the power of AI safely and effectively.
Key Takeaways
- LLMs are powerful for security tasks but depend heavily on input quality: DARPA's AICC program demonstrated LLMs' ability to autonomously find and patch 18 zero-days in complex, unseen open-source projects for an average cost of $152 per bug.
- Decompilers are a critical bottleneck for LLM-driven binary analysis: LLMs struggle with raw binaries and assembly, requiring decompiled code. However, current decompilers often produce structurally dissimilar output compared to original source code.
- Structural similarity directly impacts LLM effectiveness: Even minor structural differences in decompiled code (e.g., rearranged
ifstatements) can cause LLMs to fail at tasks like patching, leading to incorrect fixes or the introduction of new, worse vulnerabilities. - Graph Edit Distance (GED) quantifies decompiler quality for LLMs: GED measures the structural difference between a decompiled function's control flow graph and its original source. Successful LLM patching generally occurs with a GED of 3 edits or less, while failures are common at 12 edits or more.
- Current decompilers have significant room for improvement: Even leading decompilers like IDA Pro and Angr produce average GEDs of around 22 edits on common binaries, indicating a substantial deviation from source code likeness. However, Angr's improvement from 45 to 22 edits in two years shows progress is achievable.
- Defenders must be cautious and proactive: When using LLMs for binary analysis, security teams should use multiple decompilers, always manually validate LLM-generated patches, and advocate for decompiler developers to prioritize reducing Graph Edit Distance as a key metric for future development.
About the Speaker(s)
Zion Leonahenahe Basque is a final-year PhD student at Arizona State University, currently active on the academic job market. His research focuses on enhancing the understandability, fixability, and security of programs. To achieve these goals, he delves into various interdisciplinary areas, including decompilation, AI for security (specifically in contexts related to the DARPA AI Cyber Challenge, AICC), and reverse engineering, exploring how hackers analyze programs to perform advanced operations. Zion is an active member of the Shellfish CTF team, participating in competitive hacking, and conducts his research within the SEFCOM research lab at Arizona State University.
Reviews
Dr. Zero (Offensive Security Researcher) — STRONG ACCEPT
Solid research that quantifies something the binary-analysis-plus-LLM crowd has been hand-waving about: decompiler output structure matters enormously for downstream LLM reasoning. The GED metric is a real contribution, the Nginx case study is damning, and the failure mode—LLM patches that pass the POC but introduce worse bugs—is exactly the kind of thing practitioners need to internalize before they ship autonomous patching pipelines.
Heather Calloway (CISO) — STRONG ACCEPT
This is consequential research for anyone building or buying LLM-powered security tooling. The core finding—that decompiler structural fidelity directly determines whether your AI produces correct patches or introduces new vulnerabilities—has immediate implications for procurement, validation workflows, and trust calibration in automated binary analysis.