Score Matching with Missing Data
Josh Givens (PhD student), Song Liu, Henry Reeve (Nanjing University)
Overview
This talk, presented by Song Liu and spearheaded by his PhD student Josh Givens, introduces a novel framework for applying score matching techniques to datasets afflicted by missing values. Titled "Score Matching with Missing Data," the research addresses a critical gap in the application of powerful generative models and statistical inference methods to real-world, incomplete data. Score matching is a foundational component of many modern machine learning paradigms, including diffusion models and energy-based models, which are increasingly vital for tasks like high-fidelity data generation, image synthesis, and robust inference.
Key moments
- 0:00 Introduction to score matching and its applications
- 2:00 Problem setup: Extending score matching to missing data
- 4:00 Concept of marginal score matching explained
- 5:00 The challenge: high-dimensional marginalization is hard
- 5:50 Solution 1: Approximating marginal density via importance sampling
- 7:00 Solution 2: Gradient-first approximation using imputation model
- 8:00 Approximating conditional expectation with variational inference
Score Matching with Missing Data
Speakers: Josh Givens, Song Liu, Henry Reeve
Conference: ICML 2025
YouTube: https://slideslive.com/39044072
Overview
This talk, presented by Song Liu and spearheaded by his PhD student Josh Givens, introduces a novel framework for applying score matching techniques to datasets afflicted by missing values. Titled "Score Matching with Missing Data," the research addresses a critical gap in the application of powerful generative models and statistical inference methods to real-world, incomplete data. Score matching is a foundational component of many modern machine learning paradigms, including diffusion models and energy-based models, which are increasingly vital for tasks like high-fidelity data generation, image synthesis, and robust inference.
The core challenge tackled by this work is how to learn the full score function—the gradient of the logarithm of a probability density function—when only a partial observation of the underlying data is available. Traditional score matching approaches assume complete data, rendering them unsuitable for common scenarios where sensor failures, data collection errors, or privacy concerns lead to incomplete records. By extending score matching to explicitly handle missing data, this research provides a principled theoretical and algorithmic foundation that promises to unlock the full potential of score-based models in domains previously hindered by data incompleteness.
The significance of this contribution cannot be overstated. In an era where data quantity often outweighs quality, and real-world datasets are inherently noisy and incomplete, methods that can robustly operate on partial information are invaluable. This work not only enhances the applicability of score matching but also paves the way for more resilient and generalizable AI systems that can learn comprehensive data representations even from fragmented observations, thereby improving data generation, imputation, and graphical model estimation in practical settings.
Background
▶ Watch: Introduction to score matching and its applications (0:00)
Score matching is a fundamental technique in statistical modeling and machine learning, serving as the backbone for various advanced methods. At its heart, the objective of score matching is to learn the score function of a probability distribution p(x), which is defined as the gradient of its log-density: S(x) = ∇_x log p(x). A score model, denoted S_θ(x) = ∇_x log q_θ(x), is then trained to approximate this true score function, where q_θ(x) is a parameterized density model. A crucial aspect is that q_θ(x) does not need to be normalized, as the normalizing constant is independent of x and thus vanishes upon differentiation.
The training objective for score matching involves minimizing the Fisher divergence between the true score function and the score model, expressed as E_p[(S(x) - S_θ(x))^2]. A key theoretical result in score matching is that this objective can be transformed into a more tractable form that does not explicitly depend on the unknown true score function S(x). This tractable objective is typically given by E_p[tr(∇_x S_θ(x)) + 0.5 ||S_θ(x)||^2], making it feasible to train score models without direct access to p(x). Score matching has found widespread application in diverse machine learning tasks, including the training of energy-based models (EBMs), the burgeoning field of diffusion models for generative tasks, graphical model estimation, and mode-seeking clustering.
Despite its versatility and power, traditional score matching is predicated on the assumption that all data observations are complete. This assumption rarely holds true in real-world scenarios, where missing data is a pervasive issue. The problem addressed by this research is therefore to extend score matching to settings where data is incomplete. The setup defines a ground truth random variable x, which is never directly observed. Instead, a corrupted version x' is observed, along with a set of indices λ that indicate which coordinates of x are present. Specifically, x'_λ are the observed entries and are faithful copies of x_λ, while x'_{¬λ} (unobserved entries) are represented as NAN (Not a Number). A critical assumption made in this work is Missing Completely At Random (MCAR), meaning the set of observed indices λ is entirely independent of the ground truth variable x. The ultimate goal is to leverage these partially observed samples (x') to learn the full score function S(x), encompassing both observed and unobserved dimensions, which is essential for downstream tasks like full data generation or imputation.
Key Findings
▶ Watch: Concept of marginal score matching explained (4:00)
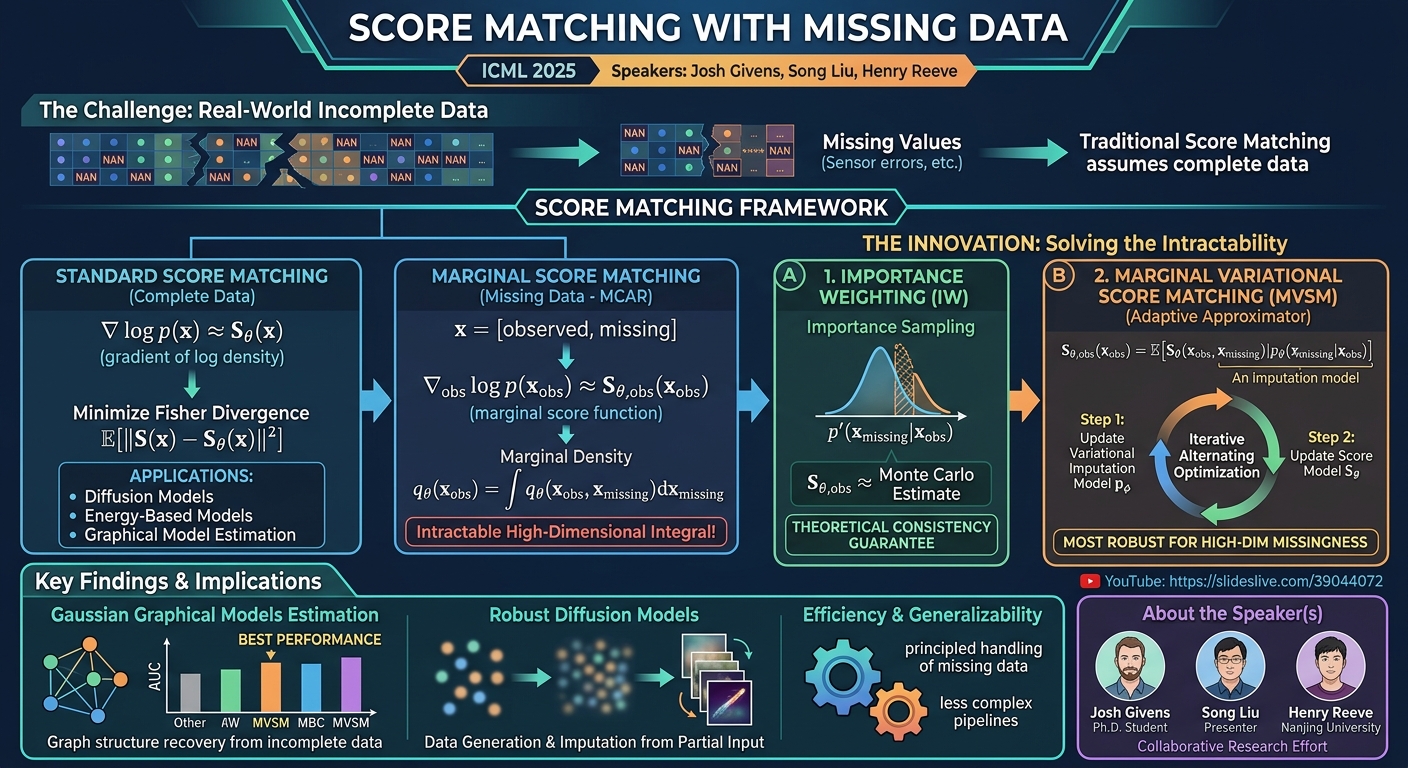
The central innovation of this work is the introduction of Marginal Score Matching (MSM), a principled approach to extend score matching to the missing data setting. The core idea is to match a marginal score model to the marginal score function of the observed data. Specifically, for a given set of observed indices λ, the marginal score function is defined as S_λ(x_λ) = ∇_{x_λ} log p(x_λ), and the corresponding marginal score model is S_θ,λ(x_λ) = ∇_{x_λ} log q_θ(x_λ). Here, q_θ(x_λ) represents the marginalized version of the joint density model q_θ(x), obtained by integrating out all unobserved entries x_¬λ: q_θ(x_λ) = ∫ q_θ(x_λ, x_¬λ) dx_¬λ. Similar to standard score matching, the MSM objective minimizes the Fisher divergence between these marginal quantities and can also be translated into a tractable form.
However, a significant computational hurdle arises: the marginalization integral ∫ q_θ(x_λ, x_¬λ) dx_¬λ is often high-dimensional and intractable, especially when a large number of entries are missing. To overcome this, the authors propose two distinct algorithmic solutions:
- Importance Weighting (IW) Approximation: This approach directly approximates the intractable marginal density model
q_θ(x_λ)using importance sampling. By rewriting the integral as an importance-weighted expectation, and assuming the ability to sample from an importance distributionp'(x_¬λ | x_λ), the marginal density and its score can be approximated. A key finding here is the theoretical justification for this method: the estimated score parameter is proven to be consistent in terms of marginal Fisher divergence, and this consistency result is backed by a finite sample bound on the estimation error. While theoretically sound, the practical effectiveness of importance sampling can diminish rapidly in very high-dimensional settings.
- Marginal Variational Score Matching (MVSM): This second solution takes a "gradient-first" approach, motivated by the limitations of IW in high dimensions. It leverages an algebraic identity that rewrites the marginal score model
S_θ,λ(x_λ)as a conditional expectation of the full joint score modelS_θ(x)with respect to the conditional distribution of missing entries given observed entries,p_θ(x_¬λ | x_λ). This conditional distribution is effectively an imputation model. The gradient of the overall MSM objective with respect to the model parametersθcan then be expressed in a similar form involving this conditional expectation. To approximate this expectation, the authors propose using variational inference. A variational imputation modelp_φ(x_¬λ | x_λ)is optimized to approximatep_θ(x_¬λ | x_λ)by minimizing their Fisher divergence, which, crucially, can also be expressed as a function of the joint score modelS_θ(x), avoiding further marginalizations. The MVSM algorithm then proceeds with an alternating optimization scheme, iteratively refining the variational imputation model and updating the score model parameters.
Empirically, the proposed methods were evaluated on the task of estimating Gaussian graphical models, a domain where inferring dependencies from potentially incomplete data is crucial. The results indicate that the proposed approaches, particularly the Marginal Variational Score Matching algorithm, significantly outperform existing or baseline methods, achieving the best performance in terms of AUC (Area Under the Curve) for graph structure recovery. This suggests that MVSM's adaptive variational approximation strategy makes it more robust to varying degrees of data missingness compared to the direct importance weighting approach.
Technical Deep Dive
▶ Watch: The challenge: high-dimensional marginalization is hard (5:00)
The technical foundation of this work rests on extending the principles of score matching to accommodate missing data. We begin by revisiting the core definitions and then elaborate on the proposed solutions.
The score function of a probability distribution p(x) over a d-dimensional vector x is defined as S(x) = ∇_x log p(x). A parameterized score model S_θ(x) = ∇_x log q_θ(x) aims to approximate S(x). The training objective is to minimize the Fisher divergence: D_F(p || q_θ) = E_p[||S(x) - S_θ(x)||^2_2]. A key result, often attributed to Hyvärinen (2005), allows for a tractable objective that bypasses the need for S(x): L(θ) = E_p[tr(∇_x S_θ(x)) + 0.5 ||S_θ(x)||^2_2].
In the context of missing data, we observe x_λ, the subset of x corresponding to indices in λ, while x_¬λ are unobserved. The goal is to learn the full score function S(x) from x_λ. The proposed Marginal Score Matching (MSM) criterion adapts the objective to the observed marginal distribution.
The marginal score function for observed entries x_λ is S_λ(x_λ) = ∇_{x_λ} log p(x_λ).
The corresponding marginal score model is S_θ,λ(x_λ) = ∇_{x_λ} log q_θ(x_λ), where q_θ(x_λ) is the marginal density obtained by integrating out the unobserved components from the joint model q_θ(x):
q_θ(x_λ) = ∫ q_θ(x_λ, x_¬λ) dx_¬λ.
The MSM objective is then L_λ(θ) = E_p[tr(∇_{x_λ} S_θ,λ(x_λ)) + 0.5 ||S_θ,λ(x_λ)||^2_2], where the expectation is taken over the observed marginal distribution p(x_λ).
The primary technical challenge lies in computing S_θ,λ(x_λ) because of the high-dimensional integral required to obtain q_θ(x_λ).
Solution 1: Importance Weighting (IW) Approximation
The first proposed solution directly approximates the marginal density q_θ(x_λ) using Monte Carlo integration with importance sampling.
The integral q_θ(x_λ) = ∫ q_θ(x_λ, x_¬λ) dx_¬λ can be rewritten as an expectation:
q_θ(x_λ) = E_{p'(x_¬λ | x_λ)} [ q_θ(x_λ, x_¬λ) / p'(x_¬λ | x_λ) ],
where p'(x_¬λ | x_λ) is an arbitrary importance sampling distribution for the missing data given the observed data.
If we can sample x_¬λ^(m) for m=1,...,M from p'(x_¬λ | x_λ), then q_θ(x_λ) can be approximated by:
q_θ(x_λ) ≈ (1/M) Σ_{m=1}^M [q_θ(x_λ, x_¬λ^(m)) / p'(x_¬λ^(m) | x_λ)].
The marginal score model S_θ,λ(x_λ) is then approximated by differentiating this Monte Carlo estimate. This approximation is plugged into the MSM objective, and θ is optimized.
A significant theoretical contribution of this approach is the proof of consistency: the estimated score parameter θ is consistent in terms of marginal Fisher divergence, with a finite sample bound on the estimation error. However, the practical efficacy of importance sampling degrades rapidly as the dimensionality of x_¬λ increases, limiting its applicability to scenarios with a modest amount of missing data.
Solution 2: Gradient-First Approximation via Marginal Variational Score Matching (MVSM)
To address the limitations of IW in high dimensions, the second solution, Marginal Variational Score Matching (MVSM), takes a more sophisticated approach. It leverages a key identity that relates the marginal score model to the full joint score model through a conditional expectation:
S_θ,λ(x_λ) = E_{p_θ(x_¬λ | x_λ)} [ S_θ(x_λ, x_¬λ) ].
Here, p_θ(x_¬λ | x_λ) = q_θ(x_λ, x_¬λ) / q_θ(x_λ) is the conditional distribution of the missing entries given the observed entries, which effectively acts as an imputation model. This identity means that the marginal score can be computed by averaging the full score over possible imputations of the missing data.
The gradient of the MSM objective L_λ(θ) with respect to θ also involves this conditional expectation, generalizing a known result by Hyvärinen and Sahani (2016). The challenge then shifts from directly computing the marginalization integral to approximating this conditional expectation E_{p_θ(x_¬λ | x_λ)} [ S_θ(x) ].
MVSM tackles this by employing variational inference. A variational imputation model p_φ(x_¬λ | x_λ) (parameterized by φ) is introduced to approximate the true conditional distribution p_θ(x_¬λ | x_λ). This p_φ is learned by minimizing the Fisher divergence between p_φ and p_θ. Crucially, this Fisher divergence can itself be expressed in terms of the joint score model S_θ(x), avoiding any further intractable marginalizations:
D_F(p_θ(·|x_λ) || p_φ(·|x_λ)) = E_{p_θ(x_¬λ | x_λ)}[||S_θ(x_λ,x_¬λ) - S_φ(x_λ,x_¬λ)||^2_2].
This allows for an alternating optimization strategy:
- Variational Imputation Step: Given the current score model
q_θ, update the variational imputation modelp_φby minimizingD_F(p_θ(·|x_λ) || p_φ(·|x_λ)). This involves sampling imputation samples fromp_φand using them to estimate the Fisher divergence objective. - Score Model Update Step: Given the updated
p_φ, use it to approximate the conditional expectationE_{p_φ(x_¬λ | x_λ)} [ S_θ(x) ]. This approximation is then used to compute the gradient of the MSM objectiveL_λ(θ)with respect toθ, andθis updated via gradient descent.
These two steps are iterated until convergence. The MVSM algorithm thus takes as input corrupted samples x', an initial joint density model q_θ, and an initial variational model p_φ. It iteratively refines φ to better approximate the true imputation model, and then uses this improved imputation model to guide the update of θ for the score model. This adaptive nature, where the imputation model itself is learned and refined, makes MVSM more robust to varying degrees of missingness and high-dimensional missing data problems.
Experimental Setup & Results
▶ Watch: Solution 2: Gradient-first approximation using imputation model (7:00)
The empirical validation of the proposed score matching with missing data framework focused on the task of estimating Gaussian graphical models. This is a well-established benchmark problem for assessing the ability to infer dependencies between variables from observed data, a task that becomes particularly challenging when data points are incomplete.
While the talk did not delve into the granular details of the specific datasets used, baseline comparisons, or the exact hardware configurations, it highlighted the efficacy of the proposed methods. The primary metric for evaluation was AUC (Area Under the Curve), which is commonly used to assess the performance of a classifier or, in this context, the accuracy of recovering the underlying graph structure. Higher AUC values indicate better performance in distinguishing true connections from false ones within the graphical model.
The presenter stated that "the proposed method performs the best" in these experiments. This general statement, while lacking specific numerical results in the talk, strongly implies that both the Importance Weighting (IW) and particularly the Marginal Variational Score Matching (MVSM) algorithms demonstrated superior capabilities compared to other approaches for learning score functions and subsequently inferring graphical model structures from incomplete observations. The discussion during the Q&A session further clarified that MVSM's adaptive variational inference strategy contributes to its better performance when dealing with a large number of missing entries, as it is designed to iteratively find a good approximation of the imputation distribution. In contrast, the IW method, while theoretically consistent, struggles with the high-dimensional integration involved in approximating marginal densities when many data points are absent.
The absence of detailed performance numbers and specific dataset names in the conference talk is not uncommon, as these are often reserved for the full paper or more extensive poster sessions. However, the clear assertion of superior performance, especially for MVSM, underscores the practical utility and robustness of the proposed framework in a relevant machine learning task. Ablation studies or comparisons against a wider array of baselines were not discussed, but the focus was squarely on the novel theoretical and algorithmic contributions to score matching with missing data.
Practical Implications
▶ Watch: Approximating conditional expectation with variational inference (8:00)
The development of Score Matching with Missing Data carries significant practical implications for various domains within machine learning and data science. Its ability to learn full score functions from incomplete observations directly addresses a pervasive challenge in real-world data applications.
For practitioners and model builders, this work means that powerful score-based generative models, such as diffusion models and energy-based models, can now be applied more robustly to datasets that inherently contain missing values. Previously, handling missing data with these models often required ad-hoc pre-processing steps like imputation, which could introduce biases or lose valuable information. This framework provides a principled, end-to-end method that integrates missing data handling directly into the score learning process. For instance, in diffusion models, this enables tasks like image inpainting or data generation from partially observed inputs without needing to explicitly "fill in" the blanks beforehand. It offers a more coherent and theoretically grounded pathway to generating high-quality data or completing observations.
For infrastructure teams and those deploying ML systems, the implications revolve around robustness and efficiency. Systems can be designed to be more resilient to data incompleteness, reducing the need for complex data cleaning pipelines or manual interventions. While the computational overhead of the proposed algorithms, particularly the iterative nature of Marginal Variational Score Matching (MVSM), needs to be considered, the benefit of directly learning from raw, incomplete data can outweigh these costs in many applications. The ability to estimate Gaussian graphical models from partial observations, as demonstrated in the experiments, is also crucial for tasks like causal inference, network analysis, and understanding complex system dependencies where complete data is rarely available.
However, there are important tradeoffs and limitations to consider:
- Importance Weighting (IW) is theoretically appealing due to its consistency guarantee, but its practical applicability is constrained by the dimensionality of missing data. As the number of missing entries increases, the variance of importance sampling estimators typically explodes, making it inefficient or infeasible.
- Marginal Variational Score Matching (MVSM), while algorithmically more complex, is shown to be more adaptive and robust in high-dimensional missing data scenarios. Its iterative optimization of a variational imputation model allows it to better approximate the true conditional distributions. However, the current work does not provide theoretical consistency guarantees for MVSM, which is an acknowledged open problem. This means that while it performs well empirically, its theoretical properties are less understood than IW.
- The assumption of Missing Completely At Random (MCAR) is a strong one. In many real-world settings, data might be Missing At Random (MAR) or Missing Not At Random (MNAR), where the missingness pattern depends on observed or even unobserved data, respectively. Extending this framework to MAR or MNAR settings would introduce further complexities but significantly broaden its applicability.
- The challenge of high-dimensional marginalization remains a fundamental hurdle in score matching with missing data. While MVSM offers an effective approximation strategy, the inherent difficulty of integrating over vast unobserved spaces persists as an active area of research.
In summary, this work provides a powerful and principled framework for integrating missing data handling into score-based models, opening new avenues for their application in data-rich, yet often incomplete, environments. Practitioners must carefully weigh the theoretical guarantees and computational demands of each proposed method against the specific characteristics and missingness patterns of their datasets.
Key Takeaways
- Extending Score Matching: This research successfully extends the fundamental technique of score matching to explicitly handle datasets with missing values, addressing a critical limitation for real-world applications.
- Marginal Score Matching (MSM) Criterion: The core innovation is the introduction of Marginal Score Matching, which involves matching a marginalized score model to the marginal score function of the observed data.
- Two Algorithmic Solutions: Two distinct algorithms are proposed to tackle the intractable high-dimensional marginalization integral:
- Importance Weighting (IW): A direct approximation method with theoretical consistency guarantees, but limited effectiveness in very high-dimensional missing data scenarios.
- Marginal Variational Score Matching (MVSM): A gradient-first approach that uses variational inference to approximate the conditional expectation of the joint score model, offering greater adaptivity and robustness for high-dimensional missingness.
- Robustness in High Dimensions: MVSM demonstrates superior empirical performance, particularly in scenarios with substantial missing data, by iteratively refining a variational imputation model alongside the score model.
- Practical Applicability: This framework enables the principled use of score-based generative models (e.g., diffusion models) and statistical inference (e.g., graphical model estimation) on incomplete datasets, facilitating tasks like data generation, imputation, and dependency inference from partial observations.
- Open Challenges: While significant progress is made, challenges remain, including extending theoretical guarantees to the MVSM algorithm and addressing more complex missingness mechanisms beyond Missing Completely At Random (MCAR).
About the Speaker(s)
The talk was presented by Song Liu, who acknowledged that the project was primarily led by his PhD student, Josh Givens. Josh Givens was unable to attend the conference to present the work due to an internship commitment. The research was also co-supervised by Henry Reeve from Nanjing University. This collaborative effort highlights a strong academic partnership in advancing the theoretical and practical aspects of score matching in the context of incomplete data.
Reviews
Maya Iyer (Theoretical ML Researcher) — SOLID
A competent and honestly scoped extension of score matching to the MCAR missing data setting. The Marginal Score Matching criterion is a natural formulation, the IW branch delivers a genuine finite-sample consistency result, and the MVSM branch offers a practically motivated variational approximation. The theoretical gap between the two branches — one proven, one not — is the paper's honest weak point, and the empirical validation is thin by current standards. This is solid, publishable work that will be useful to a specific community, but it is not the kind of result that reframes the problem or provides infrastructure the field broadly builds on.
Chen Zhao (Applied ML Researcher & Empiricist) — SOLID
Givens, Liu, and Reeve tackle a real and underserved problem — extending score matching to missing data settings — and the theoretical machinery is credible: the MSM criterion is principled, the IW consistency proof with finite-sample bounds is the kind of result that earns tenure committee attention, and the MVSM variational reformulation is genuinely clever in that it sidesteps further marginalization by expressing the variational fitting objective in terms of the joint score model. That said, the empirical validation reported in this talk is thin to the point of concern — a single task (Gaussian graphical model recovery), AUC as the lone metric, no specific numbers surfaced, no dataset…
→ Top-rated talks at International Conference on Machine Learning 2025
All talks from International Conference on Machine Learning 2025