Interference-aware Edge Runtime Prediction with Conformal Matrix Completion
Tianshu Huang, Arjun Ramesh, Emily Ruppel, Anthony Rowe, Carlee Joe-Wong
Conference on Machine Learning and Systems 2025 · Day 2 · Session 4: Reliable and Scalable Systems
Overview
This talk, "Interference-aware Edge Runtime Prediction with Conformal Matrix Completion," presented by Tianshu Huang, delves into the critical and complex problem of accurately predicting software workload execution times on novel hardware platforms, particularly within the challenging domain of edge and cyber-physical systems. The core innovation lies in framing this prediction challenge as a matrix completion problem, augmented with conformal prediction to provide statistical bounds on runtime, and specifically designed to account for interference effects when multiple tasks run concurrently.
Key moments
- 0:00 Introduction: Predicting workload runtime on new platforms
- 1:10 Why linear speed scaling fails for runtime prediction
- 2:40 Interference: a major challenge for runtime prediction
- 3:20 Matrix completion: the core idea for runtime prediction
- 4:00 Why matrix completion failed in cloud orchestration
- 5:00 The edge: where matrix completion becomes critical
- 5:40 Extreme heterogeneity and resource constraints of edge architectures
Interference-aware Edge Runtime Prediction with Conformal Matrix Completion
Speakers: Tianshu Huang, Arjun Ramesh, Emily Ruppel, Anthony Rowe, Carlee Joe-Wong
Conference: MLSys 2025
YouTube: https://www.youtube.com/watch?v=None
Overview
This talk, "Interference-aware Edge Runtime Prediction with Conformal Matrix Completion," presented by Tianshu Huang, delves into the critical and complex problem of accurately predicting software workload execution times on novel hardware platforms, particularly within the challenging domain of edge and cyber-physical systems. The core innovation lies in framing this prediction challenge as a matrix completion problem, augmented with conformal prediction to provide statistical bounds on runtime, and specifically designed to account for interference effects when multiple tasks run concurrently.
The work addresses a significant gap in current ML systems, where traditional performance prediction methods fall short due to the extreme heterogeneity, resource constraints, and real-time demands of edge devices. By leveraging machine learning techniques, specifically a matrix factorization approach, the researchers aim to overcome the limitations of static analysis, invasive dynamic analysis, and expensive simulators. This research is highly relevant for manufacturers and suppliers in industrial automation and automotive computing, where precise runtime estimates are crucial for optimizing hardware design, software deployment, and ensuring real-time deadlines without costly over-provisioning.
The talk highlights that while matrix completion for performance prediction has been explored in cloud computing, its application to the edge presents unique complexities that necessitate a specialized approach. The presented solution offers a data-driven, scalable method for predicting performance, even for unseen workload-platform combinations, and quantifies the uncertainty in these predictions. This capability is vital for the continued development and deployment of sophisticated AI/ML applications on the diverse and constrained hardware landscape of the modern edge.
Background
▶ Watch: Introduction: Predicting workload runtime on new platforms (0:00)
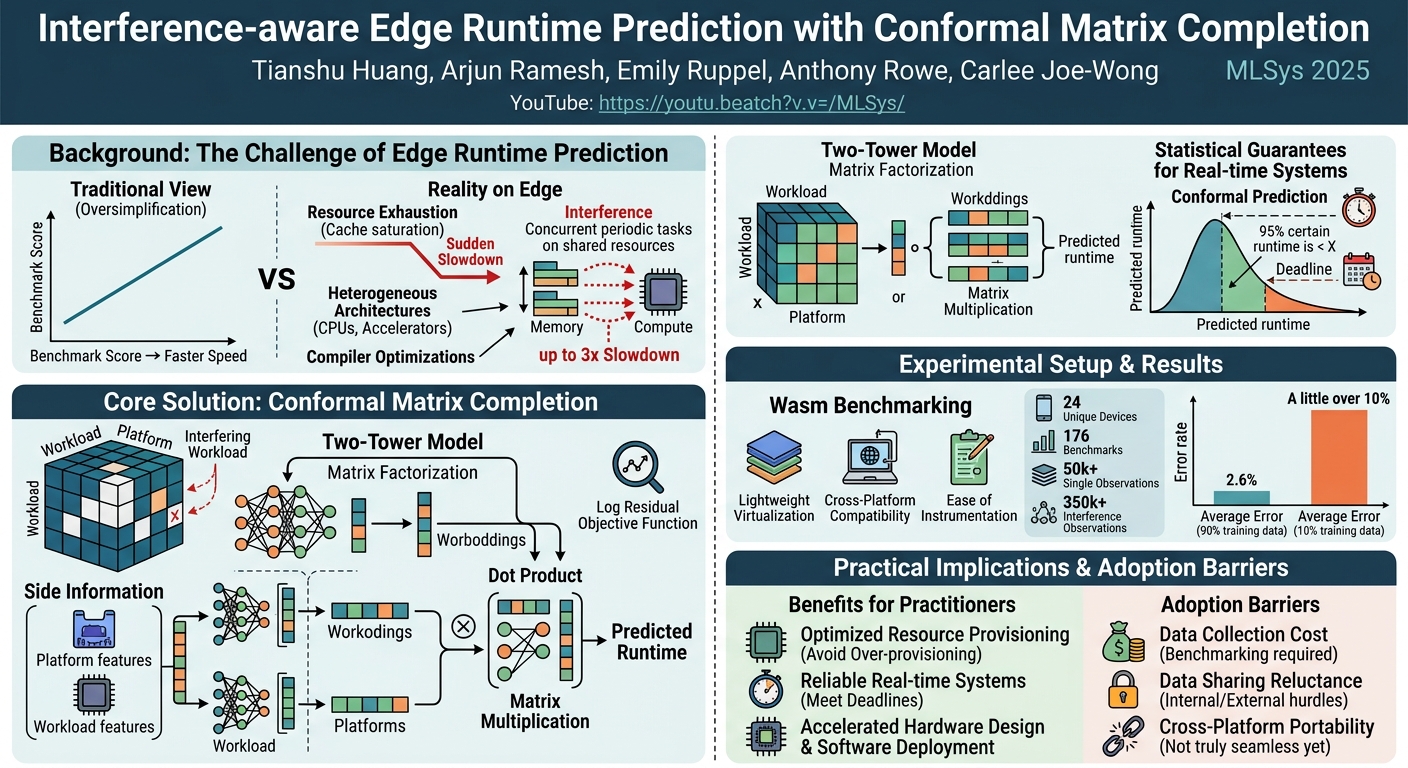
The fundamental problem addressed is predicting how a software workload will perform on a hardware platform it has not previously run on, with a specific focus on execution time. Traditionally, computer speed is often simplified to a scalar score, like a benchmark result, where a higher score implies a faster machine. This linear scaling abstraction, however, is often a significant oversimplification and can be wildly inaccurate in real-world scenarios. Even for simple microbenchmarks like matrix multiplication with varying sizes, observed execution times on different platforms do not follow a predictable linear relationship.
Several factors contribute to this unpredictability. Resource exhaustion is a common culprit; for instance, a matrix multiplication workload might perform efficiently until its data exceeds the CPU cache, leading to a sudden and significant slowdown. Heterogeneous architectures further complicate matters, as different CPUs are not merely faster versions of each other but possess vastly different micro-architectures. Furthermore, compilers introduce another layer of complexity, performing architecture-specific optimizations that can lead to unpredictable runtime behaviors.
The problem is exacerbated in multi-tasking environments by interference. When multiple tasks run concurrently, they contend for shared resources such as memory bandwidth, disk I/O, or shared compute units (e.g., on accelerators). If these tasks are periodic, as is common in edge systems, their resource utilization patterns can align in unpredictable ways, leading to highly variable and hard-to-predict slowdowns. The presented data shows that even for random pairs of benchmarks, interference can cause slowdowns of up to three times.
The idea of using matrix completion for runtime prediction is not entirely new; it was explored over a decade ago by Delicio and Kazakis for cloud computing, primarily for VM selection. However, this approach did not gain mainstream adoption in cloud orchestration for several reasons. Cloud environments, while seemingly vast, are relatively less heterogeneous compared to the edge. They feature a smaller number of platform classes with similar performance profiles, making it feasible to benchmark the most promising options directly and rule out unsuitable ones (e.g., using an H100 node for a web server). Thus, the need for sophisticated performance prediction was less acute in the cloud.
The landscape changes dramatically when considering edge cyber-physical systems. The collaboration between CMU and Bosch, focusing on industrial automation and automotive computing, highlights this distinction. Edge systems offer a far greater diversity of compute options, extending beyond AMD, Intel, or even ARM/X86 to include architectures like RISC-V and highly customized platforms with various accelerators and DSPs. These systems are typically highly resource-constrained, making interference effects more pronounced and critical. Moreover, edge systems are often real-time systems, where meeting specific deadlines is paramount, not just achieving average efficiency. This demands precise runtime prediction to avoid both deadline misses and costly over-provisioning.
Existing runtime prediction methods for edge systems largely fall into three categories:
- Static Analysis: Involves training a model for each platform. This is inherently difficult, often running into the halting problem, and usually only yields worst-case execution times (WCET) after extensive code annotation or strict coding rules.
- Dynamic Analysis: Observes a workload on one platform to predict its behavior on another. This requires invasive instrumentation on the physical device, which is often labor-intensive, device-specific, and sometimes impossible.
- Dynamic Analysis with a Simulator: Relies on a simulator to model device behavior. While avoiding physical instrumentation, simulators are often impractical or prohibitively expensive to develop and maintain for the vast array of edge hardware.
The presented work proposes a new approach that trades engineering effort for data, leveraging the classic machine learning playbook to aggregate data and implicitly learn complex performance features.
Key Findings
▶ Watch: Interference: a major challenge for runtime prediction (2:40)
The talk presents several key findings and contributions to the field of edge runtime prediction:
- Matrix Factorization for Edge Performance: The core finding is that framing runtime prediction as a matrix completion problem (workload x platform, extended to include interfering workloads) is an effective strategy for edge computing. This approach, which aggregates data from diverse workloads and platforms, can implicitly learn complex performance patterns that are difficult to measure directly.
- High Prediction Accuracy: The proposed method, based on a two-tower model with a specialized log residual objective and interference handling, achieves remarkably low average error rates. Specifically, it can achieve an average error as low as 2.6% when predicting the last 10% of a matrix after training on 90% of the data. Even with limited training data (10%), the error rate remains a respectable "a little over 10%," demonstrating robust performance across varying data availability.
- Interference-Aware Prediction: The research successfully extends matrix factorization to incorporate the highly complex and unpredictable effects of workload interference. This is crucial for resource-constrained edge systems where multiple periodic tasks often share limited resources, leading to significant slowdowns.
- Statistical Bounds with Conformal Prediction: Beyond just predicting average runtime, the method integrates conformalized quantile regression to predict statistical bounds on execution time. This is a vital capability for real-time edge systems where guarantees about maximum latency (e.g., "95% certain runtime is less than X") are more important than just an average prediction.
- Identification of Adoption Barriers: The work not only proposes a technical solution but also critically analyzes the fundamental barriers to the widespread adoption of runtime prediction methods in edge computing. These include the difficulty of precisely specifying compute capabilities and resource usage, the reluctance of organizations to share benchmarking data, and persistent challenges with true cross-platform software portability.
- Leveraging WebAssembly: The use of WebAssembly (Wasm) as an intermediate representation for benchmarks is identified as a practical enabler. It offers lightweight virtualization, cross-platform compatibility, and ease of instrumentation, significantly reducing the engineering effort typically required for diverse benchmarking.
In summary, the research demonstrates a robust, data-driven methodology for accurate and interference-aware runtime prediction on heterogeneous edge devices, while also providing a realistic assessment of the practical challenges that must be overcome for its widespread deployment.
Technical Deep Dive
▶ Watch: Matrix completion: the core idea for runtime prediction (3:20)
The technical approach hinges on the insight that runtime prediction can be modeled as a matrix completion problem. Given a matrix where rows represent workloads and columns represent platforms, and entries are observed runtimes, the goal is to predict the missing entries. This concept is extended to account for interference by considering a three-dimensional interaction: workload, platform, and interfering workload.
The core of the prediction system is a matrix factorization approach, a classic machine learning technique, specifically adapted for this domain. The fundamental idea is to aggregate performance data from all observed workload-platform pairs to implicitly learn underlying features. These features, or embeddings, represent the intrinsic characteristics of workloads and platforms that influence runtime, even if those characteristics are not explicitly measurable through instrumentation (e.g., subtle memory access patterns).
The model architecture is based on a two-tower model, a common structure in recommender systems.
- Side Information: The process begins by incorporating side information – explicit features associated with each platform and workload. This could include architectural details for platforms or resource usage patterns for workloads.
- Embedding Generation: This side information is fed into the two-tower model, which then predicts a low-dimensional embedding vector for each platform and each workload. These embeddings are essentially learned representations that capture the performance-relevant aspects of each entity.
- Prediction: The predicted runtime for a specific workload-platform pair is obtained by taking the dot product of their respective embedding vectors. This simple operation effectively models the interaction between the workload's demands and the platform's capabilities.
A crucial component is the log residual objective function. This objective was specifically designed to handle runtimes that span multiple orders of magnitude, a common occurrence when predicting execution times for diverse workloads ranging from sub-millisecond control algorithms to multi-second complex tasks. The log transformation helps normalize these wide ranges, ensuring that the model performs well across the entire spectrum. The paper further elaborates on its desirable statistical properties.
To address interference, the matrix factorization approach is extended to handle three-way interactions. Instead of a simple vector dot product for workload-platform interaction, the model incorporates a matrix multiplication in the middle to capture the more complex interplay between a workload, its platform, and an interfering workload. This allows the model to learn how specific interfering tasks impact the performance of other tasks on a given device.
Finally, to provide crucial guarantees for real-time systems, the system incorporates a conformalized quantile regression procedure. This statistical technique goes beyond predicting a single average or expected runtime. Instead, it predicts statistical bounds (e.g., a 95% confidence interval) on the runtime. This means that for a given prediction, the system can state, "we are 95% certain that your runtime will be less than X." This is invaluable in real-time embedded systems where missing a deadline can have severe consequences, and an understanding of prediction uncertainty is critical for safety and reliability.
The experimental setup leverages WebAssembly (Wasm) for running benchmarks. Wasm is highlighted as a lightweight virtualization method that compiles programs into an intermediate representation. Its advantages include:
- Diversity in Runtime Environment: Allows testing various runtime configurations without complex OS installations or Docker setups.
- Cross-Platform Compatibility: Eliminates the need to recompile benchmarks for every target architecture, simplifying the benchmarking process.
- Ease of Instrumentation: Facilitates the collection of side information about workloads with less engineering effort.
The talk clarifies that while Wasm introduces a performance overhead compared to native execution, this overhead is often minimal with aggressive ahead-of-time (AOT) compilers that translate Wasm directly to machine code. In such cases, Wasm effectively acts as an intermediate representation, and the performance characteristics, including variability, remain largely similar to native execution. This makes Wasm a suitable and practical choice for collecting diverse performance data across heterogeneous edge platforms.
Experimental Setup & Results
▶ Watch: The edge: where matrix completion becomes critical (5:00)
To validate their approach, the researchers assembled a substantial dataset and conducted extensive experiments on a dedicated heterogeneous benchmarking cluster.
Dataset and Hardware:
- The dataset comprises over 50,000 observations of single-workload runtimes.
- An additional 350,000 observations were collected specifically to study interference effects, involving multiple workloads running concurrently.
- Each workload was executed in a periodic manner, mirroring the typical behavior of tasks in real-time edge systems.
- The experiments were performed on a custom-built heterogeneous benchmarking cluster, consisting of 24 unique devices.
- A total of 176 distinct benchmarks were run across these devices.
- All benchmarks were executed using WebAssembly (Wasm), leveraging its cross-platform compatibility and instrumentation benefits.
Methodology:
- The evaluation involved splitting the collected dataset into training and testing sets.
- Varying proportions were used for training, ranging from 10% to 90% of the data, with the remaining portion used for testing. This allowed for an assessment of the model's performance under different data availability scenarios.
- The primary metric for evaluation was average error.
- The proposed method was compared against unspecified "baselines," with the claim that their method consistently outperformed them across all settings.
Headline Results:
- The model achieved a low average error of 2.6% when predicting the remaining 10% of the matrix (i.e., when 90% of the data was used for training). This indicates high accuracy when a substantial amount of training data is available.
- Even with significantly less training data, specifically when only 10% of the data was used for training and the remaining 90% needed prediction, the average error was "a little over 10%." While higher, this still represents a robust prediction capability for scenarios with limited initial benchmarks.
Addressing Extreme Tails and Limitations:
- A critical concern in real-time systems is the possibility of extreme tails in prediction errors, where a few predictions might be significantly worse than the average. The speaker acknowledged that such cases are "definitely possible," particularly when there is very little training data for specific platforms or workloads.
- To mitigate this, significant effort was invested in conformal prediction, which allows the system to quantify statistical bounds. Instead of just a point estimate, the model can provide statements like, "we are 95% certain that your runtime is going to be less than this." This is vital for embedded and real-time systems where strict deadlines must be met, offering a robust way to understand and manage prediction uncertainty.
The experimental results demonstrate the practical viability and accuracy of the conformal matrix completion approach for runtime prediction in complex, interference-prone edge environments. The use of WebAssembly for data collection further highlights a pragmatic solution to the challenges of benchmarking diverse hardware.
Practical Implications
▶ Watch: Extreme heterogeneity and resource constraints of edge architectures (5:40)
The "Interference-aware Edge Runtime Prediction with Conformal Matrix Completion" work carries significant practical implications for various stakeholders involved in the development and deployment of AI/ML on edge devices.
For Practitioners and Infra Teams:
- Optimized Resource Provisioning: The ability to accurately predict runtime, including the effects of interference, is critical for avoiding over-provisioning in resource-constrained edge systems. In environments where every penny of cost and every Watt of power matters, precise estimates ensure that hardware is specified and utilized optimally, leading to significant cost savings and improved energy efficiency.
- Reliable Real-time Systems: For real-time applications common in industrial automation and automotive computing, guaranteeing deadlines is paramount. By providing statistical bounds on runtime (e.g., "95% certain runtime is less than X"), the method allows system designers to make informed decisions about scheduling and resource allocation, ensuring that critical tasks meet their deadlines even under varying load conditions.
- Accelerated Hardware Design and Software Deployment: When developing new hardware platforms or deploying novel software combinations, the ability to predict performance without extensive physical prototyping or exhaustive benchmarking dramatically speeds up the development cycle. This enables faster iteration and reduces time-to-market for new edge products.
- Performance Troubleshooting and Debugging: While not explicitly stated, accurate prediction models can also serve as a baseline for expected performance. Deviations from predicted runtimes could signal underlying issues in software, hardware, or environmental factors, aiding in performance troubleshooting.
Tradeoffs and Limitations:
Despite its benefits, the talk candidly outlines several fundamental barriers to widespread adoption, which represent key tradeoffs and limitations:
- Data Collection Cost: The method, being data-driven, requires an initial investment in benchmarking. "You can't just download a model and expect it to work." Accurately specifying the compute capability of a platform and the resource usage of a workload (especially implicit factors like memory access patterns) necessitates collecting some amount of performance data for each new workload and platform. This upfront cost can be a barrier.
- Data Sharing Reluctance: A major hurdle is the unwillingness of organizations to share benchmarking data, even internally. The cost associated with getting data into a "shareable state" can be substantial, and early sharers may not immediately see a benefit until a critical mass of data is collected. This creates a "chicken-and-egg" problem, where the full value of a shared performance library is only realized with collective contribution. Overcoming this requires upfront investment and a collaborative ecosystem.
- Cross-Platform Portability: The prediction of hypothetical performance is only valuable if the workload can actually run on the target platform. True cross-platform portability is "not really there yet." Despite advances in lightweight virtualization technologies like Docker and WebAssembly, moving a workload seamlessly between vastly different edge platforms without significant compatibility challenges remains difficult. The trend towards better portability is positive, but until it's fully realized, software compatibility will remain a bottleneck.
- Extreme Prediction Tails: While the average error rates are low, the possibility of extreme prediction errors (tails) exists, especially when very little training data is available for a particular workload-platform combination. While conformal prediction helps quantify these bounds ("we are 95% certain..."), it doesn't eliminate the underlying variability. Practitioners must still account for these worst-case scenarios, potentially by adding safety margins, particularly in safety-critical applications.
In essence, while the technical solution offers a powerful way to predict performance, its practical implementation requires addressing organizational, data governance, and software engineering challenges. The value proposition is clear, but successful adoption hinges on collaborative efforts to build shared data libraries and continued improvements in platform-agnostic software deployment.
Key Takeaways
- Matrix Completion for Edge Runtimes: Runtime prediction for highly heterogeneous, resource-constrained edge systems can be effectively framed and solved as a matrix completion problem, extending to handle interference.
- High Accuracy with Data: The proposed matrix factorization model achieves low average error rates (e.g., 2.6% with 90% training data), demonstrating its effectiveness in predicting performance for unseen workload-platform combinations.
- Interference-Aware Prediction is Critical: The model successfully incorporates interference effects from co-running, periodic workloads, which is crucial for accurate predictions in multi-tasking edge environments.
- Statistical Bounds for Real-time Systems: Conformalized quantile regression provides statistical bounds on runtime, offering guarantees (e.g., 95% certainty) essential for meeting deadlines in real-time edge applications.
- Wasm as an Enabler: WebAssembly facilitates benchmarking across diverse edge hardware by providing lightweight virtualization, cross-platform compatibility, and ease of instrumentation, streamlining data collection.
- Adoption Barriers Remain: Key challenges for widespread adoption include the cost of initial benchmarking, the reluctance of organizations to share performance data, and ongoing issues with true cross-platform software portability.
About the Speaker(s)
The work presented is a collaboration involving Tianshu Huang, Arjun Ramesh, Emily Ruppel, Anthony Rowe, and Carlee Joe-Wong. The team operates as a collaboration between Carnegie Mellon University (CMU) and Bosch. Their research interests broadly focus on applications within industrial automation and automotive computing, indicating a strong practical orientation towards cyber-physical systems and real-world edge deployment challenges. Tianshu Huang was the primary presenter for this specific talk.
Reviews
Simon Wisk (Open Source Developer & AI Tooling Expert) — SOLID
Genuinely interesting framing of a hard problem — runtime prediction on heterogeneous edge hardware as matrix completion with conformal bounds — and the research appears real and carefully executed. But the article leaves too many implementation gaps to be actionable for engineers who want to build something similar, and the 'novelty vs. cloud prior work' story is undersold. Worth watching if you're in this exact domain; not must-see for the broader ML systems audience.
Jensen Hitch (AI Compute Platform CEO) — SOLID
Competent, honest research that solves a real problem in edge scheduling — interference-aware runtime prediction using matrix completion with conformal bounds. The framing is smart, the use of WebAssembly as an instrumentation layer is practically clever, and the statistical guarantees for real-time systems show genuine domain awareness. But this is a point solution for a narrow slice of the edge deployment problem, and the talk never reasons about what this enables at scale, what the system around the predictor looks like, or how this changes the way anyone builds. Solid academic contribution; not a platform shift.
→ Top-rated talks at Conference on Machine Learning and Systems 2025
All talks from Conference on Machine Learning and Systems 2025