VoLUT: Efficient Volumetric Streaming Enhanced by LUT-based Super-Resolution
Chendong Wang (University of Wisconsin Madison), Anlan Zhang, Yifan Yang, Lili Qiu, Feng Qian, Suman Banerjee
Conference on Machine Learning and Systems 2025 · Day 4 · Session 12: Edge and Cloud Systems
Overview
The talk introduces VoLUT, a groundbreaking system designed to address the significant challenges of streaming high-fidelity volumetric video. Volumetric video, which offers a full 3D representation of a scene allowing for six degrees of freedom (6DOF) movement, promises truly immersive experiences for applications ranging from real-time telepresence to next-generation gaming and AR/VR. However, its inherently data-heavy nature far exceeds the capabilities of most consumer internet connections, making real-time streaming impractical. VoLUT tackles this by proposing a novel approach that leverages lookup tables (LUTs) for 3D super-resolution (SR), enabling efficient and high-quality volumetric video delivery even on resource-constrained embedded devices.
Key moments
- 0:00 Introduction to volumetric video and streaming challenges
- 2:00 Limitations of current 3D Super Resolution methods
- 4:00 Introducing VoLUT: A novel LUT-based 3D SR system
- 6:00 Key insight 1: Deleted interpolation for accurate geometry
- 8:00 Quantizing 3D neighborhoods for discrete lookup table keys
- 12:00 Ultra-fast refinement via LUT memory fetch
- 13:00 Adaptive bitrate controller for smooth, consistent quality
- 16:00 VoLUT's superior visual fidelity and accuracy results
VoLUT: Efficient Volumetric Streaming Enhanced by LUT-based Super-Resolution
Speakers: Chendong Wang, Anlan Zhang, Yifan Yang, Lili Qiu, Feng Qian, Suman Banerjee
Conference: MLSys 2025
YouTube: https://www.youtube.com/watch?v=None
Overview
The talk introduces VoLUT, a groundbreaking system designed to address the significant challenges of streaming high-fidelity volumetric video. Volumetric video, which offers a full 3D representation of a scene allowing for six degrees of freedom (6DOF) movement, promises truly immersive experiences for applications ranging from real-time telepresence to next-generation gaming and AR/VR. However, its inherently data-heavy nature far exceeds the capabilities of most consumer internet connections, making real-time streaming impractical. VoLUT tackles this by proposing a novel approach that leverages lookup tables (LUTs) for 3D super-resolution (SR), enabling efficient and high-quality volumetric video delivery even on resource-constrained embedded devices.
Presented by Chendong Wang from the University of Wisconsin-Madison, alongside collaborators from the University of Southern California and Microsoft Research, VoLUT represents a significant leap forward in making immersive 3D content accessible. The system distinguishes itself by introducing a two-stage SR paradigm—comprising an inflation step and a neural-based refinement step—that is both scalable and less sensitive to varying upsampling ratios. By strategically trading on-device memory for highly efficient model inference through custom-designed LUTs, VoLUT drastically reduces computational burdens associated with traditional neural network-based SR models. This innovation is critical for expanding the reach of volumetric video beyond high-end workstations to mobile and embedded platforms, fundamentally altering how these rich 3D experiences can be consumed.
The importance of VoLUT stems from its ability to bridge the gap between the immense data requirements of volumetric video and the practical limitations of network bandwidth and client-side computational power. By enabling high-quality 3D SR on devices like the Meta Quest 3 or Orange Pi class hardware, VoLUT democratizes access to immersive 6DOF content. Its contributions in efficient data handling, real-time performance, and adaptive quality control are poised to accelerate the adoption and development of volumetric applications, paving the way for a more interactive and visually rich digital future.
Background
▶ Watch: Introduction to volumetric video and streaming challenges (0:00)
Volumetric video represents a paradigm shift from traditional 2D media, offering viewers the ability to step into and freely explore a living 3D scene. Unlike flat video, it captures and renders full 3D representations, typically as point clouds or meshes, allowing users to move and look around in all six degrees of freedom—forward, backward, side-to-side, up, down, and rotate. This level of immersion is crucial for applications such as realistic telepresence, advanced gaming, and augmented/virtual reality (AR/VR) overlays, where understanding spatial relationships and interacting with the environment are paramount.
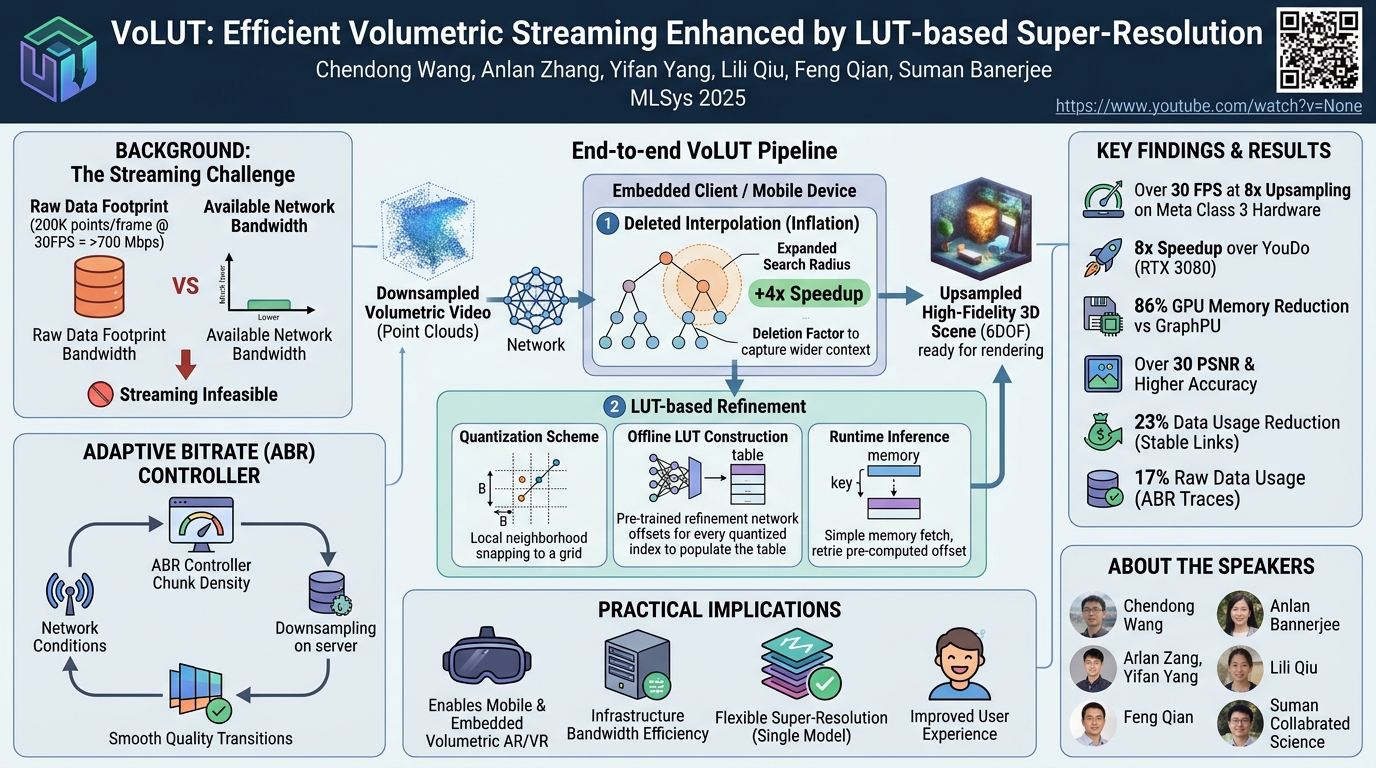
The primary challenge hindering the widespread adoption of volumetric video is its colossal data footprint. A single frame, for instance, comprising 200,000 points at 15 bytes per point, when played at 30 frames per second (FPS), translates to over 700 megabits per second (Mbps). This bitrate far exceeds the typical capacities of most home internet connections, rendering real-time 6DOF streaming infeasible with current network infrastructure. The sheer volume of data makes it a significant bottleneck for both transmission and client-side processing.
To mitigate this, prior work has explored a "clever hack": downsample the volumetric data before transmission, stream the lower-resolution content over the network, and then employ a 3D super-resolution (SR) model locally on the client device to reconstruct a high-fidelity representation. This approach is conceptually similar to NVIDIA DLSS for 2D graphics, but adapted for 3D point clouds or meshes. Systems like YouDo have demonstrated that this can indeed boost the quality of appearance. However, these existing 3D SR models come with their own set of limitations. They are typically large neural networks, demanding substantial computational resources and GPU power, which makes them unsuitable for mobile or embedded devices. Even highly optimized models impose a heavy inference burden, often requiring top-tier GPUs. Furthermore, these models are often designed for a handful of fixed upsampling ratios, meaning that a separate network must be trained and stored for each desired magnification factor. As video resolution or length increases, the storage requirements and training time for these multiple models quickly become prohibitive, limiting their practical scalability and flexibility. VoLUT emerges as a solution to these fundamental problems, aiming to provide an efficient, scalable, and mobile-friendly framework for volumetric video streaming.
Key Findings
▶ Watch: Introducing VoLUT: A novel LUT-based 3D SR system (4:00)
VoLUT introduces a novel and highly efficient system for 3D super-resolution that significantly improves the feasibility of streaming high-quality volumetric video to resource-constrained devices. Its core innovation lies in a lookup table (LUT)-based SR paradigm that replaces computationally expensive neural network inference with fast memory lookups.
The system's key findings and contributions can be summarized as follows:
- Two-Stage SR Paradigm: VoLUT proposes a new SR pipeline comprising an inflation step and a neural-based refinement step. This decoupled approach makes 3D super-resolution easier to scale and less sensitive to varying upsampling ratios, enhancing its adaptability compared to single-stage, fixed-ratio models.
- Efficient Inference via LUTs: By designing a lookup table to capture the output of the refinement network, VoLUT ingeniously trades on-device memory for drastically improved inference efficiency. This allows for the replacement of heavy neural inference, which can take seconds, with a simple constant-time memory fetch that completes in microseconds.
- Deleted Interpolation for Inflation: To overcome the geometric distortions and scalability issues of naive K-nearest neighbors (KNN) interpolation, VoLUT introduces deleted interpolation. This method samples neighbors from an expanded search radius with a "deletion factor," capturing a wider and more balanced context. Implemented with an R-tree, this approach delivers approximately a 4x speedup over vanilla interpolation while yielding smoother and more accurate reconstructions.
- Novel Quantization Scheme for LUT Keys: A crucial challenge for LUTs is converting continuous 3D neighborhood data into discrete keys. VoLUT devises an effective quantization scheme that normalizes local point groups and snaps them into a grid, generating discrete indices without introducing visual artifacts. This enables the precomputation and storage of network outputs in the LUT.
- Adaptive Bitrate (ABR) Controller: VoLUT integrates a continuous ABR controller that leverages the SR pipeline's consistent, visual-agnostic latency across upsampling factors. This controller dynamically adjusts point density per chunk to maximize visual quality and minimize storage, eliminating the abrupt quality shifts common in traditional fixed-bitrate ladders, ensuring a smooth user experience even under fluctuating network conditions.
- Exceptional Performance on Embedded Hardware: The system achieves over 30 FPS at 8x upsampling on "quad-level hardware" (e.g., Orange Pi class embedded devices, comparable to Meta Class 3 GPUs), making high-quality volumetric SR feasible on mobile and edge devices for the first time.
- Significant Speedups and Memory Savings:
- On an RTX 3080, VoLUT reaches up to 350 FPS, roughly 8 times faster than the YouDo baseline.
- It reduces GPU memory usage by 86% compared to GraphPU, primarily by offloading neural inference to LUT lookups.
- Improved Visual Fidelity and Data Efficiency: VoLUT consistently delivers over 30 PSNR and its transfer distance matches or even outperforms GraphPU, demonstrating high visual quality and geometric accuracy. In end-to-end streaming, it achieves better normalized Quality of Experience (QE) than YouDo SR, reducing data usage by 23% over stable links and by 17% (compared to raw data) under real-world ABR traces, proving its resilience in bandwidth-constrained scenarios.
These findings collectively demonstrate VoLUT's capability to deliver high-quality, real-time volumetric video experiences on a wide range of devices, fundamentally addressing the core limitations of existing streaming and super-resolution technologies.
Technical Deep Dive
▶ Watch: Quantizing 3D neighborhoods for discrete lookup table keys (8:00)
VoLUT's technical prowess stems from a meticulously designed two-stage super-resolution pipeline, an innovative lookup table (LUT) mechanism for efficient inference, and an adaptive bitrate (ABR) controller for dynamic content delivery.
Two-Stage Super-Resolution Paradigm
VoLUT's SR process is decomposed into two distinct stages: an inflation step and a refinement step. This separation allows for specialized optimization at each stage, leading to a more scalable and robust solution compared to monolithic SR models.
- Inflation Step: Deleted Interpolation
The initial inflation stage aims to increase the point density from the downsampled input. Traditional K-nearest neighbors (KNN) interpolation for point clouds often suffers from geometric distortion, especially when points are unevenly clustered. Averaging the K closest neighbors can lead to warped reconstructions and is computationally intensive at scale.
VoLUT introduces deleted interpolation to overcome these issues. Instead of simply picking the K closest neighbors, this method incorporates a "deletion factor" that effectively "bends" the search radius. For example, with K=4 and a deletion factor of 2, the system samples four neighbors from twice the normal search radius. This wider search radius allows for capturing a more balanced and representative context of the local geometry, mitigating distortion.
The implementation of deleted interpolation leverages an R-tree data structure. An R-tree is a spatial index method particularly well-suited for efficiently locating and reusing neighbor lists across multiple queries. This optimization significantly speeds up the neighbor search process, yielding approximately a 4x speedup over vanilla interpolation while producing smoother and more accurate initial reconstructions. This deleted interpolation forms the foundation upon which the subsequent refinement builds.
- Refinement Step: LUT-based Super-Resolution
The core of VoLUT's innovation lies in its refinement step, which replaces a heavy neural network inference with a lightweight lookup table operation. This addresses the computational bottleneck of prior 3D SR methods.
Quantization Scheme for Discrete LUT Keys:
The challenge for using LUTs with continuous 3D point data is to convert continuous coordinates into discrete, hashable keys. VoLUT tackles this with a novel quantization scheme:
- Local Group Normalization: For each query point, a local group of points (the query point itself and its neighbors) is identified. These local coordinates are then normalized to a canonical space, such as a 0-1 square (in 2D, as an illustrative example from the talk) or a 0-1 cube in 3D.
- Grid Overlay and Snapping: A fixed-size grid (e.g., 4x4 in 2D, or a
B x B x Bgrid in 3D, whereBis the bin size) is overlaid onto this normalized space. Each point within the local group is then "snapped" to its containing cell, yielding simple row/column/depth indices. These discrete indices, representing the relative configuration of the local neighborhood, form the unique key for the lookup table. For instance, a neighbor mapped to (0,0) and a query point to (1,1) would contribute to the overall key.
LUT Construction (Offline):
The lookup table is built offline using a pre-trained refinement network. This network's function is to take a local group of points (e.g., the output of the inflation step) and predict the offset for the central point to refine its position and improve geometry.
- The system enumerates every possible quantized neighborhood index that can be generated by the quantization scheme.
- For each unique discrete index, it simulates the corresponding continuous neighborhood configuration and feeds it through the pre-trained refinement network to compute the predicted offset.
- These (index, offset) pairs are then stored in a key-value table, which is the LUT.
LUT Inference (Runtime):
During runtime, the heavy neural network inference is entirely bypassed:
- For each point requiring refinement, its local neighborhood is extracted.
- The positions are normalized and quantized using the predefined bin size (
B) to compute the discrete index (key). - This key is then used to perform a single, constant-time memory lookup in the pre-built LUT to retrieve the corresponding offset.
- The retrieved offset is immediately applied to the point's position, completing the refinement.
Memory Considerations:
The memory footprint of the LUT grows exponentially with the number of neighbors (N) considered in the local group and the bin size (B). For example, with N=4 neighbors and a bin size of B=64, the LUT might consume around 100 MB. However, increasing the bin size to B=128 for higher fidelity can lead to a substantial 1.6 GB LUT. VoLUT prioritizes reconstruction fidelity and settles on B=128 in its production system, managing this memory trade-off to maximize visual quality without exceeding typical device memory limits. This strategy effectively shifts the computational burden from real-time GPU processing to memory bandwidth and storage, a favorable trade-off for embedded devices.
Adaptive Bitrate (ABR) Controller
Traditional volumetric video streaming relies on fixed bitrate ladders, which often result in noticeable and abrupt quality changes when network conditions fluctuate. VoLUT's SR pipeline inherently delivers consistent and visually agnostic latency across different upsampling factors, making it ideal for a continuous ABR control mechanism.
- Continuous Point Density Tracking: The ABR controller continuously monitors and tracks the point density of each volumetric chunk being streamed.
- Optimization Goals: It aims to maximize visual quality while simultaneously minimizing storage requirements.
- Smooth Quality Transitions: By dynamically adjusting the upsampling factor and transmitted point density based on real-time network conditions, the ABR controller eliminates abrupt quality shifts, providing a seamless user experience.
- Server-Side Logic: On the server side, a density-aware downsampling algorithm is applied, and the ABR decision logic is executed via a custom, lightweight protocol. The downsampled chunk is then sent to the client.
- Client-Side Processing: Upon receiving a chunk, the client executes the deleted interpolation, fetches the pre-computed offsets from the LUT for refinement, and renders the upsampled frame.
- Performance Optimizations: To maintain low latency even on embedded hardware, VoLUT leverages interest state data reuse and multi-threaded R-tree neighbor search, ensuring that the client-side processing remains highly efficient.
This comprehensive technical architecture allows VoLUT to deliver high-quality volumetric video efficiently, adaptively, and on a broad spectrum of hardware, from high-end GPUs to embedded mobile platforms.
Experimental Setup & Results
▶ Watch: Ultra-fast refinement via LUT memory fetch (12:00)
VoLUT's performance was rigorously evaluated against state-of-the-art baselines under various network conditions and on diverse hardware platforms, demonstrating its superior efficiency, quality, and adaptability.
Experimental Setup
- Volumetric Content: The evaluation utilized six distinct volumetric video sequences, each comprising approximately 100,000 points per frame. This dataset represents typical volumetric video content.
- Network Conditions: Experiments were conducted under two main scenarios:
- Fixed Bitrate Links: Stable network connections at 50 Mbps, 75 Mbps, and 100 Mbps were simulated to assess performance under consistent bandwidth.
- Real ABR Traces: Real-world adaptive bitrate (ABR) traces were used to simulate fluctuating network bandwidth, mimicking typical internet conditions and testing the resilience of VoLUT's ABR controller.
- Hardware Testbeds: To demonstrate versatility across different compute capabilities, two distinct hardware testbeds were deployed:
- Server-Side/High-End Client: An RTX 3080-powered server was used for high-performance benchmarks and simulating server-side processing.
- Embedded Client: An Orange Pi class embedded hardware device served as the target for mobile and edge deployment. This device shares the same CPU specifications as the Meta Class 3, making it a representative platform for VR/AR headsets and other resource-constrained devices.
- Baselines: VoLUT's performance was compared against three prominent state-of-the-art 3D super-resolution and streaming baselines: GraphPU, YouDo, and Velo. These baselines represent leading approaches in efficient volumetric data processing.
Metrics
The evaluation focused on several key metrics:
- Visual Fidelity: Measured using Peak Signal-to-Noise Ratio (PSNR), a common metric for image and video quality.
- Geometry Accuracy: Assessed via Transfer Distance, which quantifies the geometric difference between the reconstructed and ground-truth point clouds.
- Performance: Quantified by Frames Per Second (FPS) achieved during super-resolution and rendering.
- Resource Usage: Specifically, GPU memory consumption was measured to highlight the efficiency benefits of the LUT-based approach.
- Data Efficiency: Measured as the reduction in data usage compared to raw data or baseline systems, and overall Quality of Experience (QE).
Headline Results
The experimental results unequivocally demonstrated VoLUT's significant advantages:
- Visual Fidelity and Geometry Accuracy:
- VoLUT consistently delivered over 30 PSNR at both 2x and 4x upsampling ratios.
- Its transfer distance metrics matched and even outperformed GraphPU, indicating that VoLUT not only retains but can also improve geometric accuracy while achieving massive speedups.
- Performance on Embedded Hardware (Orange Pi / Meta Class 3):
- On the Orange Pi (with a GPU comparable to Meta Class 3), VoLUT's deleted interpolation alone delivered over 30 FPS at 8x upsampling. This is a nearly four times speedup compared to just 8 FPS for the vanilla interpolation approach, making real-time volumetric SR feasible on embedded devices.
- Performance on High-End Hardware (RTX 3080):
- On the RTX 3080, VoLUT achieved an impressive 350 FPS, which is roughly eight times faster than YouDo, showcasing its high throughput capabilities.
- GPU Memory Efficiency:
- By offloading the computationally intensive refinement step into a lookup table, VoLUT drastically cut GPU memory usage by 86% compared to GraphPU. This significant reduction is attributed to replacing large neural network inference models, which consume substantial memory, with simple memory fetches from the pre-computed LUT.
- End-to-End Streaming Efficiency:
- Under stable network links: VoLUT achieved a better normalized QE than YouDo SR while simultaneously reducing data usage by 23%.
- Under real-world ABR traces: The system maintained a better QE compared to baselines, even while streaming only 17% of the raw data. This demonstrates VoLUT's robust performance and resilience in bandwidth-constrained, dynamic network environments.
These results validate VoLUT's core design principles, proving its capability to deliver high-quality, real-time volumetric video streaming with unparalleled efficiency across a spectrum of hardware and network conditions.
Practical Implications
▶ Watch: VoLUT's superior visual fidelity and accuracy results (16:00)
VoLUT's innovations carry profound practical implications for the development and deployment of immersive 3D experiences, impacting practitioners, infrastructure teams, model builders, and deployers across various industries.
For Practitioners and Model Builders:
- Enabling Mobile and Embedded Volumetric AR/VR: The most significant implication is the democratization of high-quality volumetric video on resource-constrained devices. By achieving over 30 FPS at 8x upsampling on Meta Class 3-equivalent hardware, VoLUT makes truly immersive 6DOF experiences feasible on mobile phones, standalone VR/AR headsets, and other embedded systems. This opens up new avenues for applications in gaming, telepresence, virtual tourism, and interactive education that were previously limited by computational power.
- Flexible Super-Resolution: Unlike prior systems that required training and storing separate models for each fixed upsampling ratio, VoLUT's two-stage paradigm and continuous ABR enable flexible scaling. Model builders no longer need to manage a proliferation of models, simplifying the development and deployment pipeline. This flexibility reduces storage requirements and training time, especially as volumetric content grows in resolution and length.
- Reduced Inference Burden: The shift from real-time neural network inference to LUT-based memory lookups drastically reduces the GPU compute requirements on the client side. This allows developers to allocate precious computational resources to other tasks, such as complex scene rendering, physics simulations, or sophisticated user interactions, without compromising visual quality.
- Improved User Experience: The continuous ABR controller ensures smooth and seamless quality transitions even under fluctuating network conditions. This eliminates jarring visual artifacts and abrupt quality drops, leading to a significantly improved and more consistent user experience, critical for maintaining immersion in VR/AR environments.
For Infrastructure Teams and Deployers:
- Bandwidth Efficiency: VoLUT's ability to achieve high visual quality while reducing data usage by 17-23% compared to baselines is a game-changer for infrastructure teams. This means that high-fidelity volumetric streams can be delivered over typical home internet connections, lowering the barrier to entry for users and reducing the strain on network infrastructure. It makes large-scale deployment of volumetric services more economically viable.
- Scalability of Services: The reduced data footprint and client-side computational demands mean that service providers can scale their volumetric video offerings to a wider audience without incurring prohibitive server-side bandwidth costs or requiring users to have high-end gaming PCs.
- Edge Computing Benefits: The efficiency of VoLUT makes it well-suited for edge computing scenarios, where processing can occur closer to the user on local devices or nearby edge servers, further reducing latency and network load.
Tradeoffs and Limitations:
- On-Device Memory Footprint: The primary tradeoff for the massive inference speedup is an increased on-device memory footprint for the lookup tables. While VoLUT carefully manages this (e.g., 1.6 GB for a bin size of 128), it is a consideration for devices with extremely limited RAM. Future work might explore compression techniques or dynamic loading of LUT segments.
- Precomputation Overhead: The LUTs must be precomputed offline, which requires a one-time computational cost. However, this is amortized over many inference operations and is a standard practice for many optimization techniques.
- Generalizability to Other 3D Representations: While the speaker noted that the core ideas could be applied to other neural rendering pipelines like NeRF or 3D Gaussian splatting due to shared data structures (point cloud-like representations), specific adaptations would be needed. Factors such as limiting search space and handling potentially different feature sets per point would need to be tackled, implying that VoLUT is currently optimized for explicit point cloud representations.
- Complexity of Quantization: Designing the optimal quantization scheme without introducing visual artifacts for increasingly complex geometries or higher precision requirements can be challenging.
In summary, VoLUT provides a robust, efficient, and flexible framework that dramatically lowers the technical barriers to entry for volumetric video. Its practical implications span from enabling next-generation mobile AR/VR experiences to making high-fidelity 3D content streaming a reality for the masses, ultimately accelerating the adoption of immersive media.
Key Takeaways
- VoLUT enables efficient volumetric video streaming on embedded devices, achieving over 30 FPS at 8x upsampling on hardware comparable to Meta Class 3.
- The system employs a novel two-stage super-resolution paradigm involving deleted interpolation for initial inflation and lookup table (LUT)-based refinement for precise geometry.
- A crucial innovation is the quantization scheme that maps continuous 3D neighborhoods into discrete keys, allowing for fast, constant-time LUT lookups that replace computationally expensive neural network inference.
- VoLUT delivers significant performance benefits, including an 8x speedup over YouDo on an RTX 3080 and an 86% reduction in GPU memory usage compared to GraphPU.
- The integrated continuous Adaptive Bitrate (ABR) controller optimizes visual quality and bandwidth, reducing data usage by 17-23% while maintaining a high Quality of Experience (QE) under real-world network fluctuations.
- This work makes high-quality, 6DOF volumetric video experiences accessible on mobile and bandwidth-constrained platforms, significantly broadening the potential applications for immersive media.
About the Speaker(s)
The talk was presented by Chendong Wang from the University of Wisconsin-Madison. The research behind VoLUT is a collaborative effort, a joint work with researchers from the University of Wisconsin-Madison, the University of Southern California, and Microsoft Research, highlighting a multidisciplinary approach to solving complex problems in volumetric video streaming. The team includes Anlan Zhang, Yifan Yang, Lili Qiu, Feng Qian, and Suman Banerjee.
Reviews
Simon Wisk (Open Source Developer & AI Tooling Expert) — SOLID
VoLUT is a legitimately interesting systems paper — replacing neural inference with LUT lookups for 3D super-resolution is a clever engineering trade-off, and the embedded hardware results are the kind of thing that makes a practical difference. But the write-up reads like an abstract padded into a talk summary, and the gap between 'this is interesting research' and 'here's how you build it' is wide enough that I couldn't reproduce the core quantization scheme or LUT construction from what's described. Solid MLSys work, but presented at a level of abstraction that limits its usefulness to engineers who want to extend or adapt it.
Jensen Hitch (AI Compute Platform CEO) — SOLID
VoLUT is a competently executed systems paper that addresses a real constraint — the bandwidth and compute gap between volumetric video data rates and what embedded hardware can actually handle. The LUT-based inference substitution is a clever engineering trade, and the two-stage SR pipeline with the ABR controller shows genuine end-to-end thinking. This is honest, practical work that will matter to engineers building volumetric streaming pipelines for AR/VR. But it stops short of a platform-level insight. The memory-compute tradeoff is well-understood territory, the quantization scheme is incremental over existing LUT SR literature from 2D imaging, and the generalizability questions — to…
→ Top-rated talks at Conference on Machine Learning and Systems 2025
All talks from Conference on Machine Learning and Systems 2025