Redefining Website Fingerprinting Attacks with Multi-Agent LLMs
Chuxu Song (Paper author · Rutgers University), Dheekshith Dev Manohar Mekala (Paper author · Rutgers University), Hao Wang (Paper author · Rutgers University), Richard P. Martin (Paper author · Rutgers University)
Privacy Enhancing Technologies Symposium (PETS) 2026 · Day 3 · Caribou
Overview
This talk, "Redefining Website Fingerprinting Attacks with Multi-Agent LLMs," presented by Richard P. Martin, addresses critical shortcomings in contemporary website fingerprinting (WF) research. The speakers from Rutgers University and the University of Illinois at Urbana-Champaign highlight two significant issues: the page boundary problem, where modern web design invalidates traditional assumptions about distinct page loads, and the pervasive realism problem, where synthetic training data leads to misleadingly high attack accuracies. The research proposes a novel approach to generate more realistic browsing traffic using multi-agent Large Language Models (LLMs), offering a more robust methodology for evaluating WF attack efficacy.
Key moments
- 0:00 Introduction and core problems in website fingerprinting
- 2:20 Reframing fingerprinting: Identify websites, not individual pages
- 3:15 The realism problem and three data collection methods
- 5:40 Scripted data leads to total accuracy collapse on human traffic
- 7:00 LLM agent architecture: high-level reasoning, low-level control
- 8:10 Agent-generated data effectively augments human training data
- 9:10 Conclusion: Avoid scripted data, use humans or LLM agents
Redefining Website Fingerprinting Attacks with Multi-Agent LLMs
Speakers: Chuxu Song (Paper author, Rutgers University), Dheekshith Dev Manohar Mekala (Paper author, Rutgers University), Hao Wang (Paper author, Rutgers University), Richard P. Martin (Paper author, Rutgers University)
Conference: PETS
YouTube: https://www.youtube.com/watch?v=-PVgLsl-pdU
Overview
This talk, "Redefining Website Fingerprinting Attacks with Multi-Agent LLMs," presented by Richard P. Martin, addresses critical shortcomings in contemporary website fingerprinting (WF) research. The speakers from Rutgers University and the University of Illinois at Urbana-Champaign highlight two significant issues: the page boundary problem, where modern web design invalidates traditional assumptions about distinct page loads, and the pervasive realism problem, where synthetic training data leads to misleadingly high attack accuracies. The research proposes a novel approach to generate more realistic browsing traffic using multi-agent Large Language Models (LLMs), offering a more robust methodology for evaluating WF attack efficacy.
The presentation underscores the enduring privacy risk posed by website fingerprinting, even when traffic is encrypted. An observer can infer visited websites by analyzing metadata such as packet sizes, inter-packet spacing, and packet direction. However, the talk argues that much of the existing research, while demonstrating high accuracy in controlled environments, fails to reflect real-world user behavior. By introducing LLM-driven agents to simulate human browsing patterns, the authors not only expose the limitations of current research but also offer a pathway toward more accurate and actionable privacy assessments.
The work is significant because it challenges the foundation of many prior WF studies, advocating for a paradigm shift in data generation and attack modeling. By reframing the attack to identify entire websites rather than individual pages and demonstrating the profound impact of data realism, the researchers provide a crucial update to a long-standing privacy problem. This re-evaluation is essential for both attackers seeking to refine their techniques and, more importantly, for defenders aiming to develop effective countermeasures against realistic threats.
Background
▶ Watch: Introduction and core problems in website fingerprinting (0:00)
Website fingerprinting has been a recognized privacy threat for a considerable time. The core concept revolves around a passive network observer analyzing encrypted IP packet traffic to infer which website a user is visiting. Even with robust encryption, the metadata associated with traffic—specifically the size of packets, the time intervals between them (inter-packet spacing), and whether they are incoming or outgoing—can be distinctive enough to identify specific online activities. Historically, attackers have trained machine learning models, often neural networks like Convolutional Neural Networks (CNNs), on this metadata to classify web traffic.
Traditional WF research has largely relied on an assumption of "full page loads," where a user navigates to a distinct web page, generating a burst of traffic that can be neatly labeled and analyzed. This model assumed clear session boundaries, allowing researchers to repeatedly script page loads and collect consistent training data. However, the modern web has evolved significantly. Websites now frequently employ technologies like infinite scrolling, Single Page Applications (SPAs), and dynamic, interactive content that blurs the lines between distinct "pages." Users often remain on a single URL for extended periods, interacting with content that fetches data asynchronously without full page reloads. This fundamental shift renders the "page boundary" concept largely obsolete for accurate traffic labeling and attack modeling.
Beyond the page boundary issue, the talk identifies a more pervasive and critical challenge: the realism problem. A significant portion of WF research utilizes synthetic or scripted data for training and testing their models. This scripted data is typically generated by automated tools that follow predefined sequences of actions, such as loading a page, clicking a specific link, or filling out a form. While such methods are efficient for generating large volumes of data, they often fail to capture the nuanced, unpredictable, and highly variable patterns of actual human browsing behavior. This disconnect leads to a skewed understanding of attack efficacy, where models trained and tested on unrealistic data report artificially high accuracies, misrepresenting the true privacy risks and the effectiveness of potential defenses. The speakers argue that this pervasive reliance on unrealistic data has led the community to misleading conclusions about the capabilities of WF attacks.
Key Findings
▶ Watch: The realism problem and three data collection methods (3:15)
The research presented in this talk yielded several critical findings that fundamentally challenge the current state of website fingerprinting (WF) research and propose a more realistic path forward.
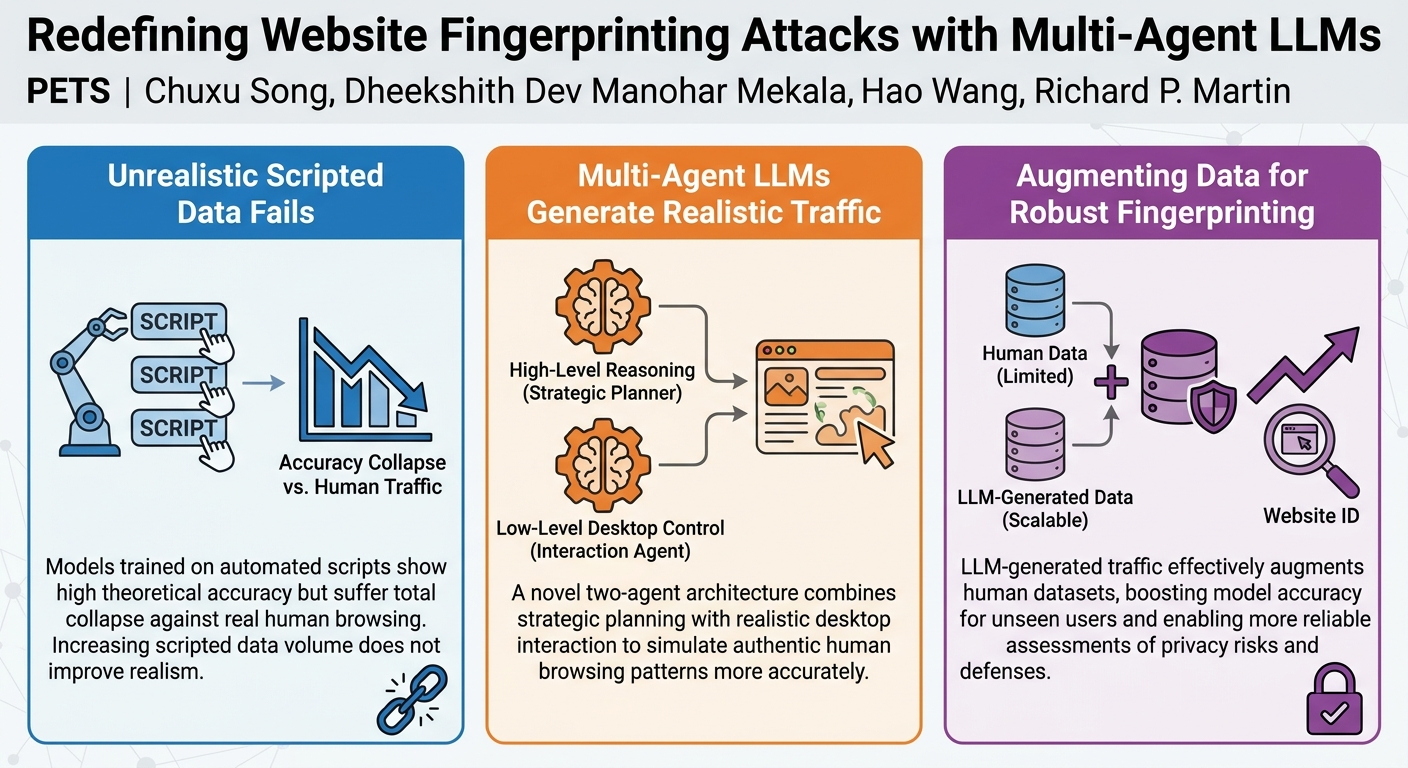
Firstly, the most impactful finding concerns the realism problem in training data. The researchers demonstrated a stark accuracy collapse when WF models are trained on scripted data (generated by automated tools like Puppeteer) and then tested against human-generated traffic. While models trained and tested on scripted data showed "enormously high accuracy," this performance plummeted dramatically when exposed to real human browsing patterns. This unequivocally proves that scripted data is "highly unrealistic" and leads to "very misleading" results regarding the actual efficacy of WF attacks against real users.
Secondly, the talk debunked the notion that sheer volume can compensate for realism. The researchers investigated whether increasing the amount of scripted data would improve classification accuracy when testing against human traffic. Their findings indicated that more scripted data does not lead to an increase in accuracy in this cross-dataset evaluation. This reinforces the conclusion that the quality and realism of the training data are paramount, not just its quantity.
Thirdly, a significant contribution is the successful development and validation of multi-agent LLMs for generating more realistic browsing traffic. Unlike scripted data, traffic generated by these LLM-driven agents showed promising results. When trained on agent-generated data and tested on human data, the accuracy improved significantly compared to models trained on scripted data. Furthermore, the agent-generated data proved valuable for data augmentation: when added to a limited set of human training data, it consistently improved the accuracy of WF models, especially in scenarios where a user's traffic was not part of the initial training set (a leave-one-out scenario). This indicates that the LLM agents generate traffic that is genuinely "representative of human traffic."
Fourthly, the research introduced a pragmatic redefinition of the WF attack model. Acknowledging the obsolescence of distinct page boundaries in modern web design (due to infinite scrolling, SPAs, etc.), the authors reframed the attack to identify the destination website from a continuous stream of 5,000 consecutive packets, rather than attempting to pinpoint individual pages. This redefinition reflects a more realistic and still privacy-impacting attack scenario, moving away from "convoluted problems" associated with session and page load boundaries.
Finally, the study also explored the impact of these different data generation methods in an open world model setting, where the attacker needs to identify a website from a larger, undefined set of possibilities, as opposed to a closed world model where all possible websites are known. They found that while moving to an open world model generally causes an accuracy drop (around 6-8% for human-only data), augmenting the training set with agent-generated data helped mitigate this drop, further underscoring the utility of LLM-driven traffic generation for robust WF research.
Technical Deep Dive
▶ Watch: Scripted data leads to total accuracy collapse on human traffic (5:40)
The technical core of this research lies in its meticulous approach to data generation and its innovative use of multi-agent LLMs to address the pervasive realism problem in website fingerprinting (WF). The authors meticulously constructed three distinct datasets to evaluate the impact of data realism on WF attack accuracy.
The first and most representative dataset was human-generated traffic. This involved hiring 30 participants who were instructed to browse 20 specific websites according to a set of instructions. Over 100 hours of actual human browsing traffic were recorded. This dataset served as the ground truth for evaluating the realism of other data generation methods, as it captured the inherent variability and unpredictability of real user interactions.
The second dataset comprised scripted data, generated using Puppeteer. Puppeteer is a Node.js library that provides a high-level API to control headless Chrome or Chromium over the DevTools Protocol. Researchers typically use Puppeteer to automate browser tasks, such as navigating to pages, clicking elements, and submitting forms. While efficient for generating large volumes of data, the talk demonstrated that this method produces traffic patterns that are highly artificial and unrepresentative of human behavior. The evaluation showed that WF models trained on this data achieved high accuracy when also tested on scripted data, but suffered a "total accuracy collapse" when tested against human traffic. This highlighted the significant disconnect between automated scripts and human browsing patterns.
The most innovative aspect was the creation of the third dataset, generated by Cloud Agents, powered by Large Language Models (LLMs). The key to the success of these agents was a multi-agent architecture, a crucial design choice. Initially, the researchers attempted to use a single agent for all tasks, which "failed." They found it necessary to break the task down into two distinct agents:
- High-level LLM-E Agent: This agent was responsible for reasoning about high-level goals. It used text-based reasoning, much like a human planning their browsing session or deciding what information to seek. This agent would determine the overall objective, for example, "research quantum computing" or "find a recipe for lasagna."
- Low-level Control Agent: This agent used the Claude computer API to actually control the desktop environment. Unlike Puppeteer, which interacts directly with the browser's internal API, this agent simulated a person moving a mouse, clicking, and typing within the operating system's graphical user interface. This approach allowed for a much more realistic simulation of human interaction, capturing nuances like pauses, varied click speeds, and deviations from perfectly optimized paths that are absent in direct browser automation.
The separation of reasoning and control was critical. The high-level agent provided the strategic intent, while the low-level agent translated that intent into realistic, observable desktop interactions. This multi-agent system allowed for the generation of traffic that more closely mimicked human browsing patterns, as evidenced by its ability to augment human training data and improve WF model accuracy.
Regarding the attack model, the researchers consciously reframed the problem. Instead of attempting to identify specific web pages, which is increasingly difficult with modern web architecture, they focused on identifying the destination website. The attack model assumes an observer can capture a continuous stream of 5,000 consecutive packets at any point within a user's session (whether TCP or QUIC). This redefinition sidesteps the complexities of determining page load boundaries or parsing the Document Object Model (DOM), making the attack model more robust and applicable to contemporary web usage patterns. The evaluation involved a "zoo of website fingerprinting models" — various neural network architectures commonly used in WF research — to ensure the findings were generalizable across different attack implementations.
Demo / Proof of Concept
▶ Watch: Agent-generated data effectively augments human training data (8:10)
While the talk did not feature a live, interactive demonstration in the traditional sense, the core proof of concept (PoC) presented was the successful development and validation of the multi-agent LLM system capable of generating realistic web browsing traffic. The very existence and performance of these agents, as detailed in the experimental results, served as the PoC for their utility in redefining website fingerprinting (WF) research.
The demonstration of this PoC was primarily through the comparative analysis of the three distinct datasets: human-generated, scripted (Puppeteer), and LLM-agent generated traffic. The efficacy of the LLM agents was empirically proven by showing:
- The significant accuracy collapse of WF models when trained on scripted data and tested on human data, highlighting the problem the LLM agents aimed to solve.
- The improved performance of WF models when trained on LLM-agent data and tested on human data, indicating that the LLM agents generate more representative traffic than traditional scripted methods.
- The ability of LLM-agent data to augment human training data, leading to increased WF model accuracy, especially in challenging leave-one-out scenarios where a specific user's traffic was not explicitly part of the training set. This demonstrated the practical utility of the agents in creating more robust and generalizable training datasets.
The technical architecture of the multi-agent LLMs, involving a high-level LLM-E agent for strategic reasoning and a low-level control agent using the Claude computer API for realistic desktop interaction, was the conceptual demonstration of how such a system could be engineered. The fact that this split architecture "didn't work very well" without the separation served as a crucial part of the PoC, illustrating the complexity involved in realistically mimicking human behavior and the specific technical innovation required to achieve it. This empirical validation through experimental results effectively served as the demonstration of the agents' capabilities and their potential to revolutionize how WF research data is generated.
Defensive Implications
▶ Watch: Conclusion: Avoid scripted data, use humans or LLM agents (9:10)
The findings of this research carry profound implications for defenders engaged in countering website fingerprinting (WF) attacks. The most critical takeaway is the urgent need to re-evaluate existing WF defense mechanisms and their underlying assumptions. If, as demonstrated, WF models trained on unrealistic scripted data achieve artificially high accuracies, it follows that defenses developed and tested against such models might be over-engineered or misaligned with actual threat landscapes. Defenders could be investing resources into mitigating attacks that are far less effective in the real world than benchmark results suggest.
Firstly, defenders must prioritize the use of realistic training data for both developing and evaluating WF defenses. This means moving away from easily generated scripted traffic and towards either human-generated traffic or, as this research proposes, sophisticated LLM-generated traffic that more accurately mimics human browsing patterns. Any defense mechanism — whether it's traffic shaping, padding, or timing obfuscation — should be rigorously tested against data that reflects the unpredictable and varied nature of real user interactions. Without this, defenses risk being effective only against theoretical, rather than practical, adversaries.
Secondly, the rise of sophisticated multi-agent LLMs for traffic generation presents a double-edged sword. While beneficial for researchers to create realistic datasets, it also implies that attackers could leverage similar LLM technologies to generate more potent and realistic WF attack traffic. This capability could make it easier for adversaries to develop highly effective WF models without the expense and logistical challenges of collecting vast amounts of human-generated data. Defenders should therefore anticipate an evolution in attack sophistication, where future WF attacks are less reliant on simplistic, predictable patterns and more on adaptive, human-like behaviors. This necessitates defenses that are robust against subtle, dynamically generated traffic anomalies rather than just overt, scripted signatures.
Thirdly, the redefinition of the WF attack model to focus on website identification rather than specific page identification should guide defensive strategies. Instead of trying to protect against precise page inference, which may be less relevant given modern web design, defenders should concentrate on broader website-level obfuscation. This might involve techniques that make it difficult to distinguish between different websites based on their overall traffic characteristics, rather than focusing solely on individual page loads.
Finally, security researchers and practitioners should be wary of relying solely on published WF accuracy numbers if the underlying data generation methodology is not realistic. A critical assessment of the data sources used in any WF study is paramount. The "garbage in, garbage out" principle articulated by the speakers serves as a stark warning: misleading benchmarks can lead to misguided defensive efforts. The community needs to embrace standardized, realistic datasets or methodologies for generating such data to foster truly effective WF defense research and deployment.
Key Takeaways
- Scripted data leads to misleading WF accuracy: Website fingerprinting models trained and tested solely on automatically generated scripted data show artificially high accuracies, which collapse significantly when tested against real human browsing traffic.
- More scripted data does not improve realism: Simply increasing the volume of unrealistic scripted data does not enhance the accuracy of WF models when applied to human-generated traffic, underscoring the qualitative importance of data realism over quantity.
- Multi-agent LLMs generate more realistic traffic: A novel multi-agent architecture, combining a high-level LLM for reasoning with a low-level agent using the Claude computer API for desktop control, can generate web browsing traffic that is more representative of human behavior.
- LLM-generated data can augment human data: Traffic generated by these sophisticated LLM agents can effectively augment limited human-generated training datasets, leading to improved accuracy for website fingerprinting models, particularly in realistic scenarios where a user's traffic is not seen during training.
- Redefining the WF attack model: The talk advocates for reframing website fingerprinting to focus on identifying the destination website from a continuous packet stream (e.g., 5,000 packets), rather than attempting to pinpoint individual pages, which is increasingly unrealistic with modern web design.
- Urgent need for realistic methodologies: The website fingerprinting research community must adopt more realistic data generation and evaluation methodologies to accurately assess privacy risks and develop effective, real-world defensive countermeasures.
About the Speaker(s)
The research presented in this talk is the collaborative effort of several individuals from Rutgers University and the University of Illinois at Urbana-Champaign. The primary paper authors, Chuxu Song and Dheekshith Dev Manohar Mekala, are graduate students at Rutgers University who, unfortunately, could not attend the conference. Their significant contributions were acknowledged by the presenter. Hao Wang, a professor at the University of Illinois at Urbana-Champaign, is also a key collaborator and paper author. The presentation at PETS was delivered by Richard P. Martin, a professor at Rutgers University, who introduced the work and its critical findings to the audience. The team's collective expertise spans privacy, network security, and machine learning, evident in their detailed analysis of website fingerprinting vulnerabilities and proposed solutions.
Reviews
Dr. Zero (Offensive Security Researcher) — MUST SEE
Richard P. Martin gets on stage at PETS and politely tells the website fingerprinting community their last decade of research is based on bullshit. By proving that Puppeteer-scripted traffic causes a total accuracy collapse against real human PCAPs, they finally kill the archaic 'page load boundary' myth. They also found a rare valid use for LLMs: using the Claude computer API to physically drive a desktop and generate realistic dataset noise.
Heather Calloway (CISO) — STRONG ACCEPT
This research exposes a fundamental flaw in how the industry models website fingerprinting risk, proving that historical accuracy metrics collapse against real human traffic. By using multi-agent LLMs to simulate actual browsing, the authors provide a much-needed reality check on privacy threats. It is required reading for any team building, buying, or threat-modeling network privacy defenses for high-target user fleets.
→ Top-rated talks at Privacy Enhancing Technologies Symposium (PETS) 2026
All talks from Privacy Enhancing Technologies Symposium (PETS) 2026